1School of Physical and Mathematical Sciences, Nanyang Technological University, Singapore 2Institute of Automation, Chinese Academy of Sciences, Beijing, China 3University of Chinese Academy of Sciences, Beijing, China 4Zhongguancun Academy, Beijing, China 5Southeast University, Jiangsu, China 6Department of Artificial Intelligence, Westlake University, Zhejiang, China 7School of Computer and Communication Engineering, University of Science and Technology Beijing, China 8College of Computing and Data Science, Nanyang Technological University, Singapore
* Shiyu Hu and Xuchen Li contributed equally to this work.
Five independent descriptions capture what people notice differently. One consensus reference captures what they share. FIOVA uses both to evaluate video captions.
Evaluating open-ended captions for medium- to long-duration videos is difficult because people differ in what they attend to, how they segment events, and how they describe them. Existing benchmarks often provide multiple references, but variation and shared content are rarely modeled as distinct evaluation objects.
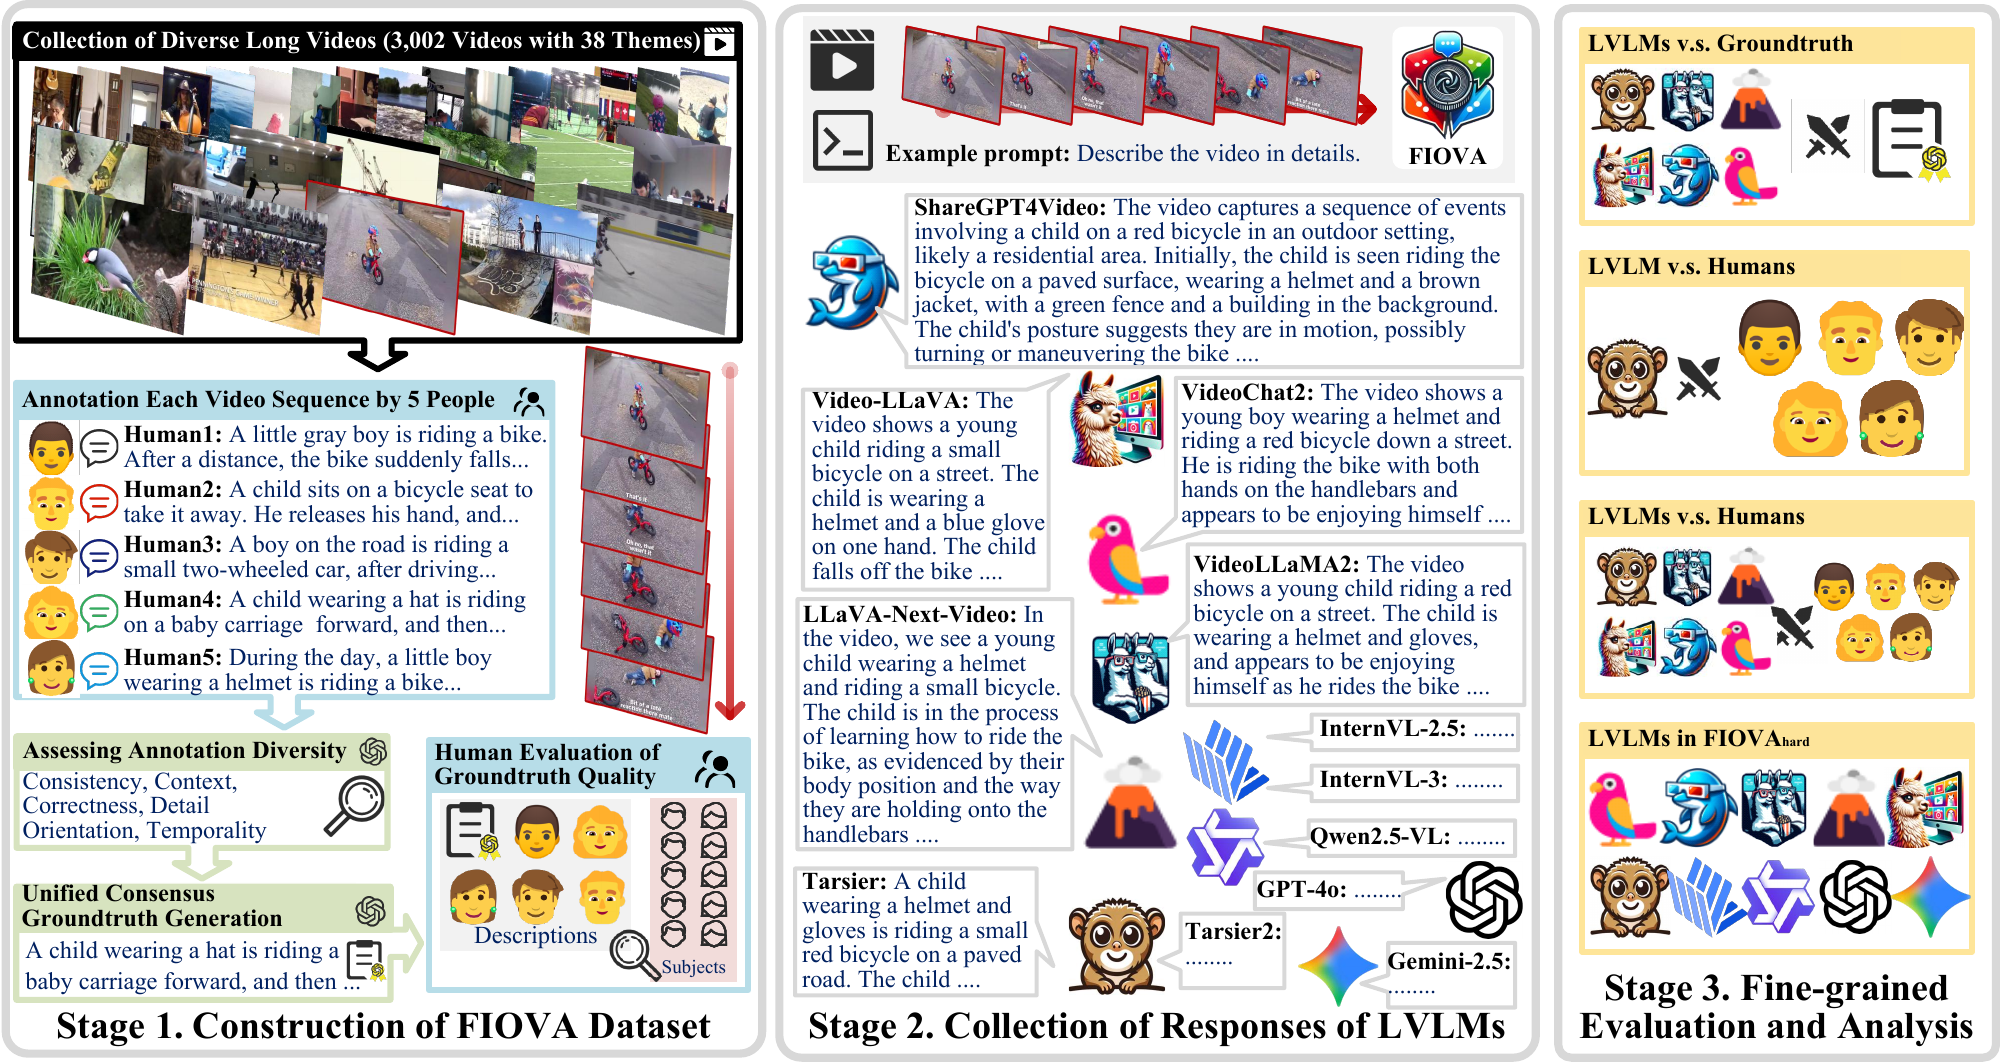
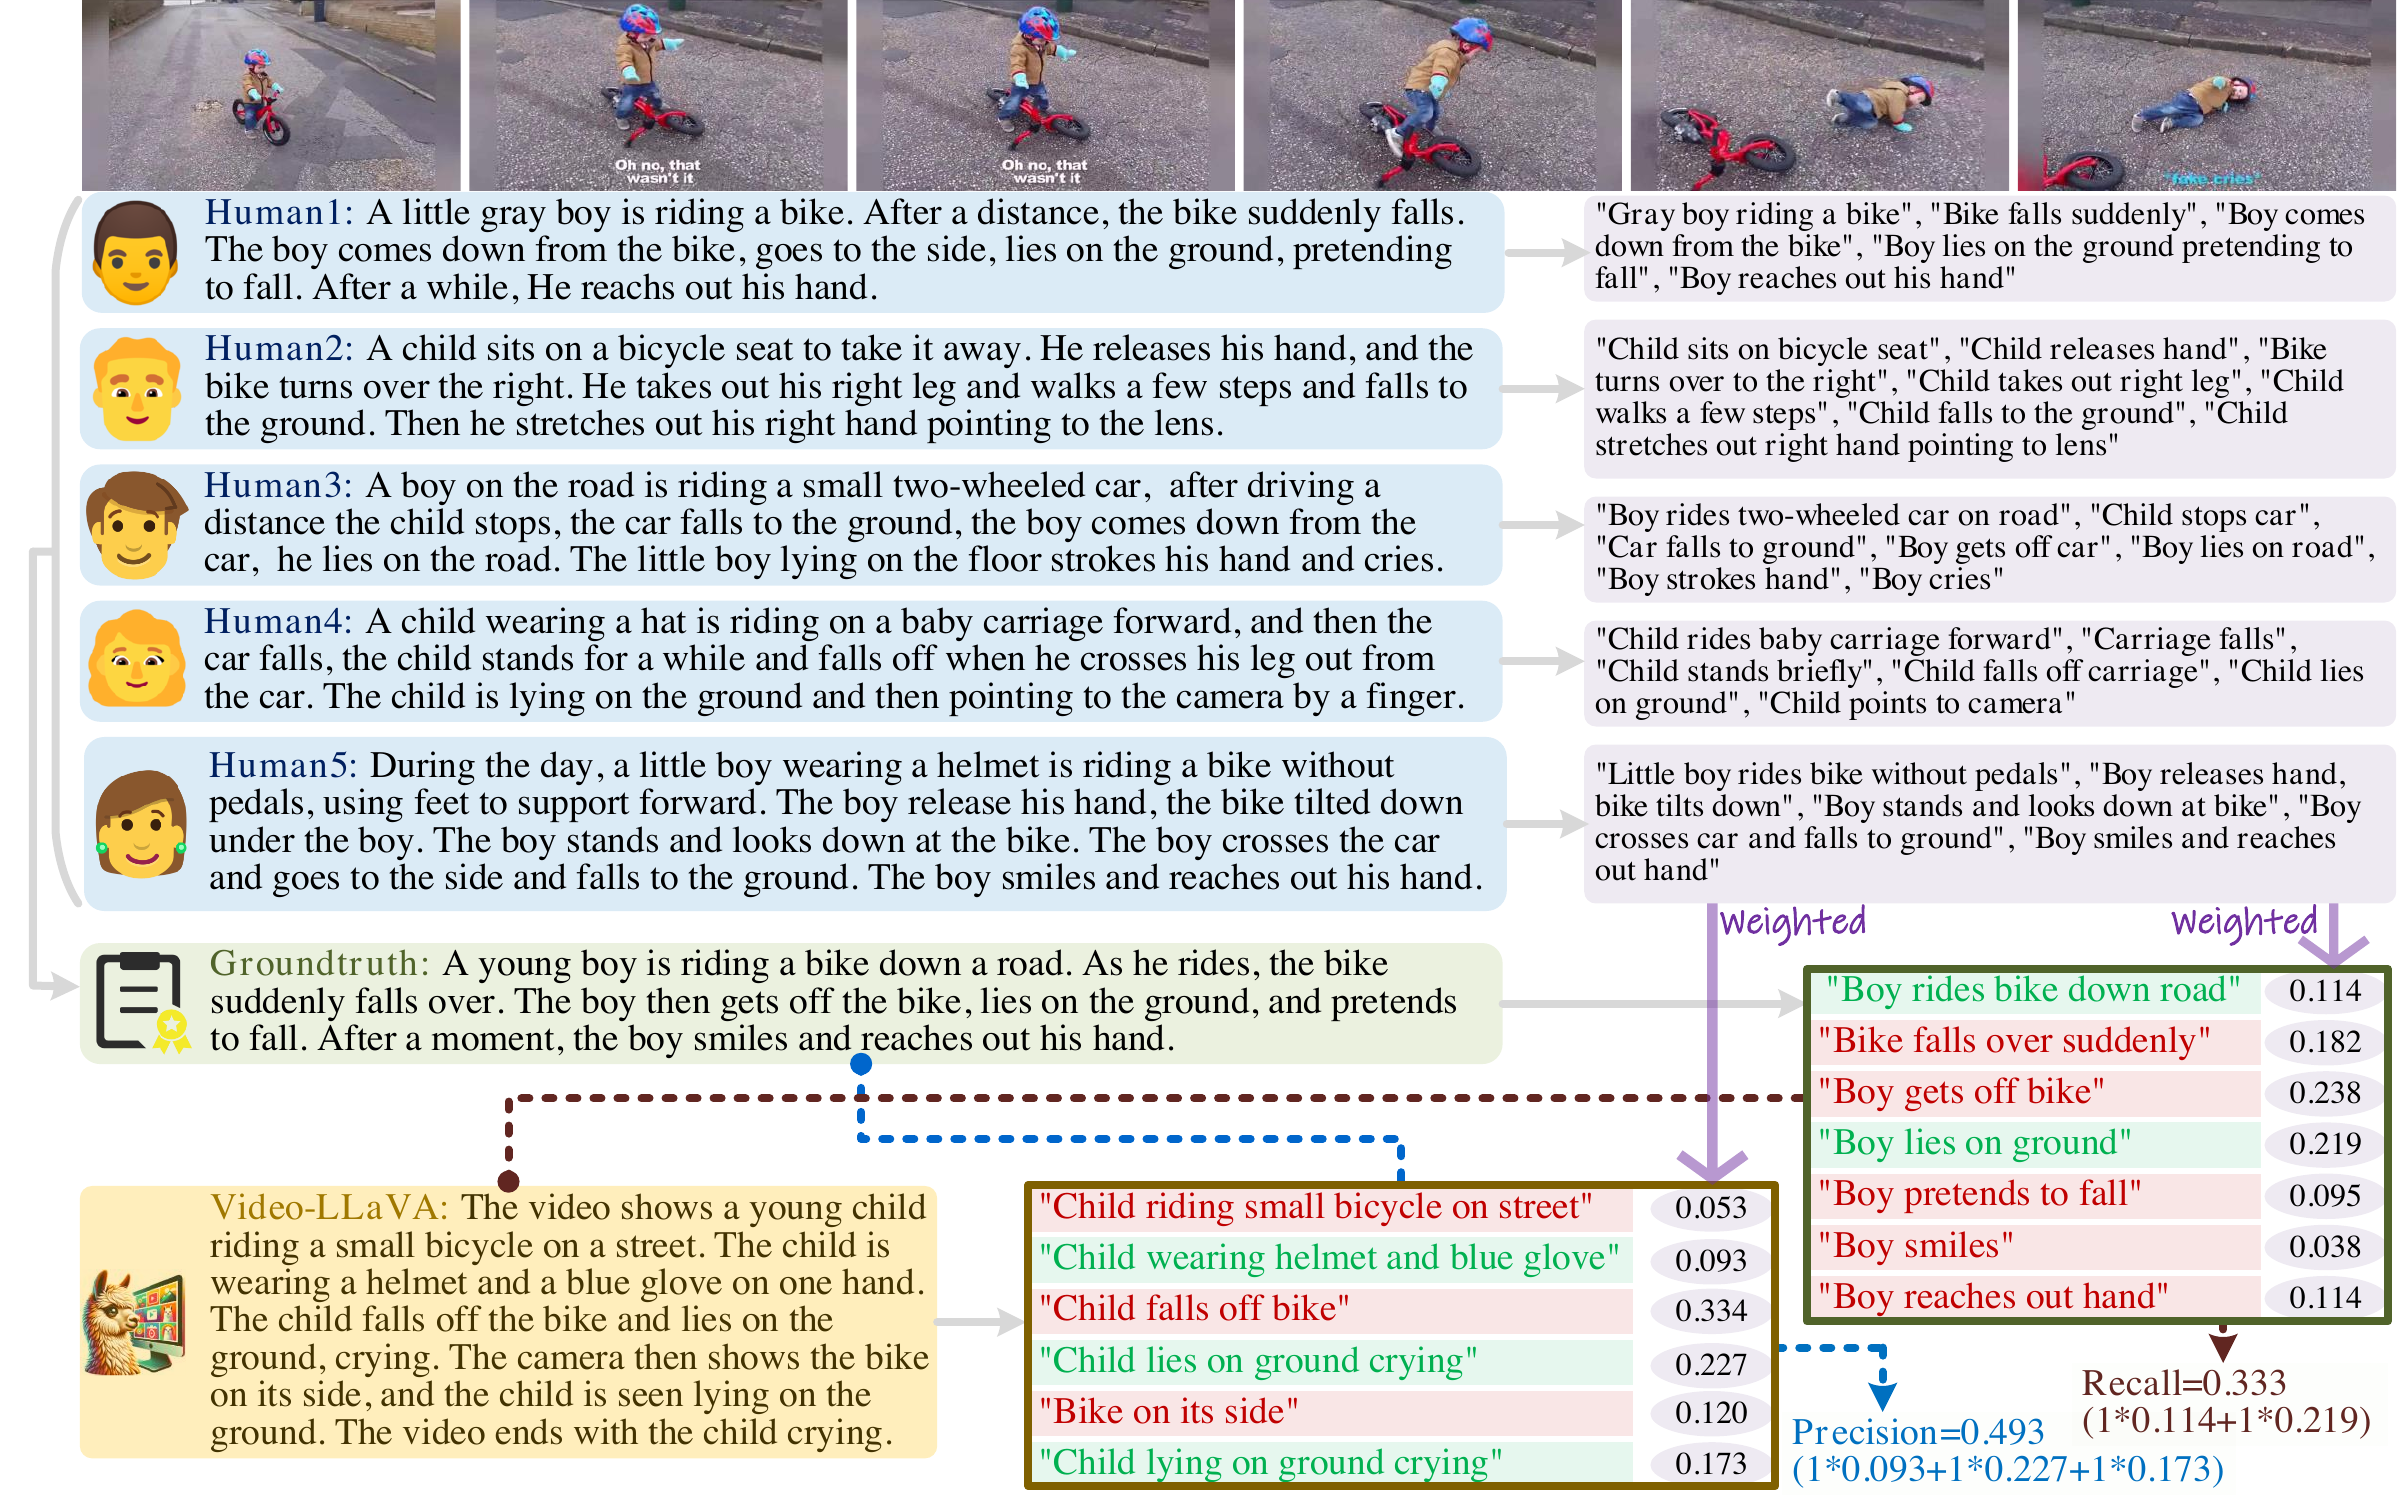
FIOVA retains five independent human captions for every video. A Unified Consensus Groundtruth (UCG) organizes their shared content into a fixed reference. FIOVA-DQ then measures event support and coverage with importance weights guided by the five human descriptions. Batch-Ranking compares model behavior across levels of human disagreement.
The FIOVA workflow: dataset construction, LVLM response collection, and evaluation. Select image to enlarge.
Retain variation
Use the original descriptions to characterize human disagreement and form evaluation strata.
Evaluate shared content
Use UCG as the common reference, with human-guided importance weights for individual events.
Compare model behavior
Evaluate six baselines across the full benchmark and twelve models on its high-disagreement subset.
Data and annotation
The FIOVA dataset
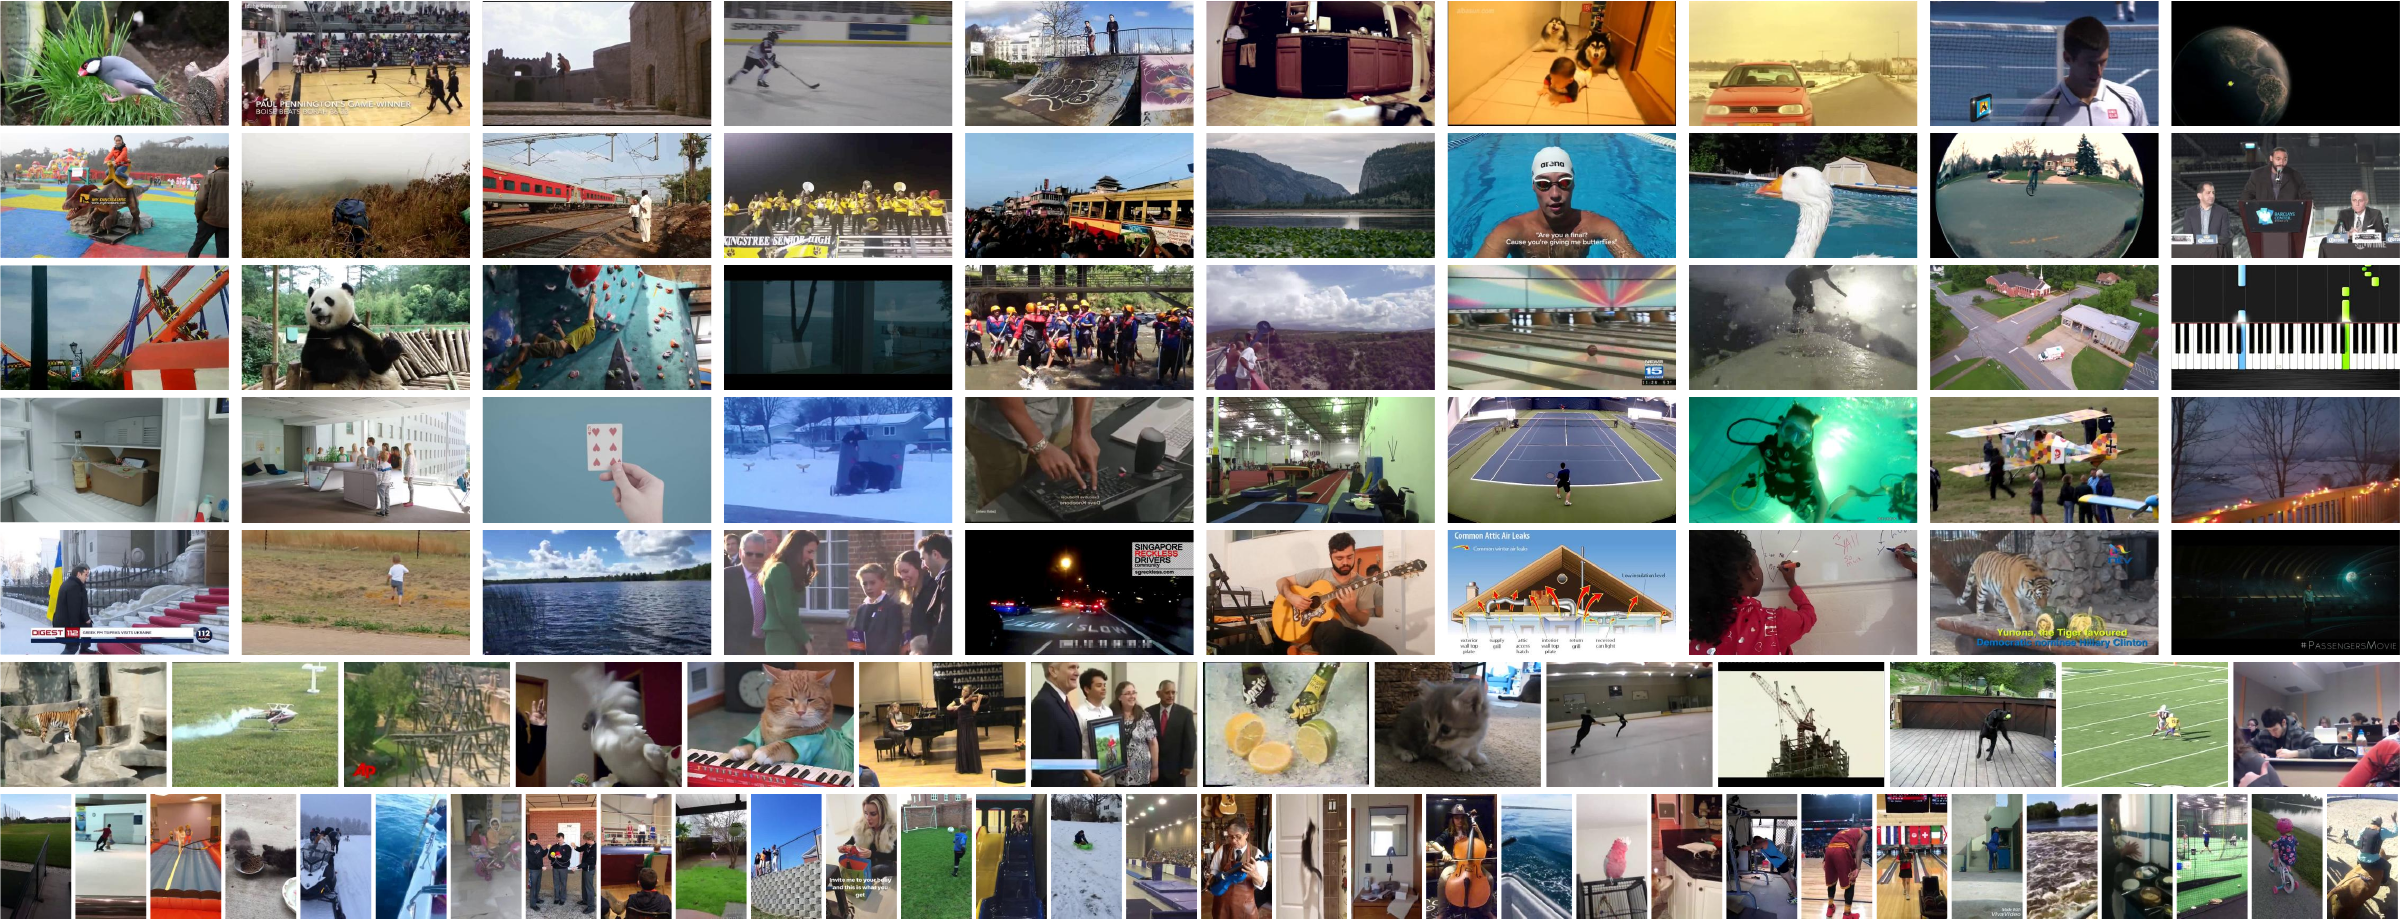
FIOVA contains 3,002 videos across 38 themes, averaging 33.6 seconds. Five annotators independently describe each video, capturing different perspectives on the same visual content.
The collection pairs 15,010 human captions with 3,002 Unified Consensus Groundtruth (UCG) references. Each caption undergoes a three-stage quality review.
Representative examples from FIOVA (main-paper Fig. 2), illustrating its thematic and visual diversity. Select image to enlarge.
Eight fixed disagreement strata
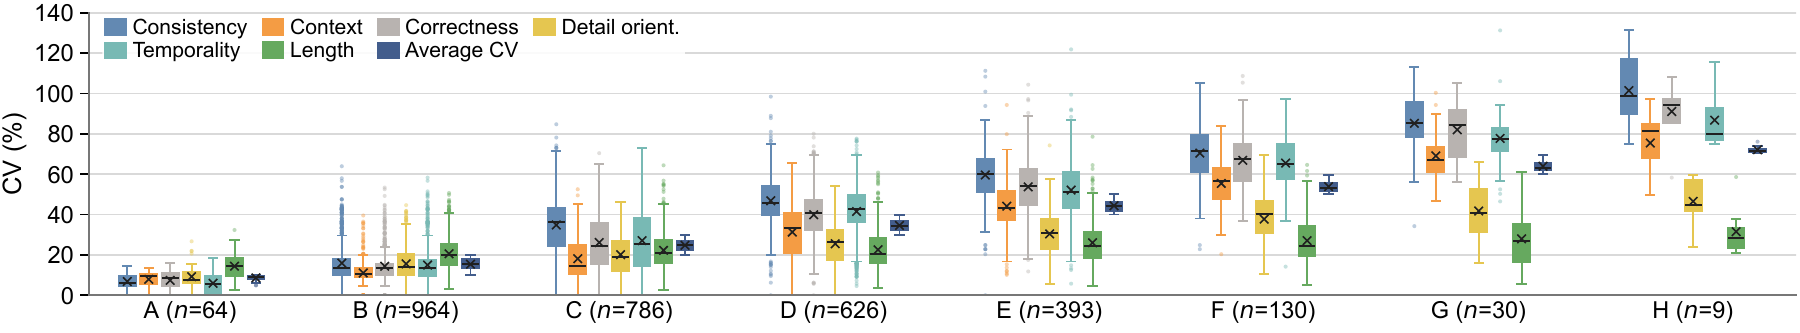
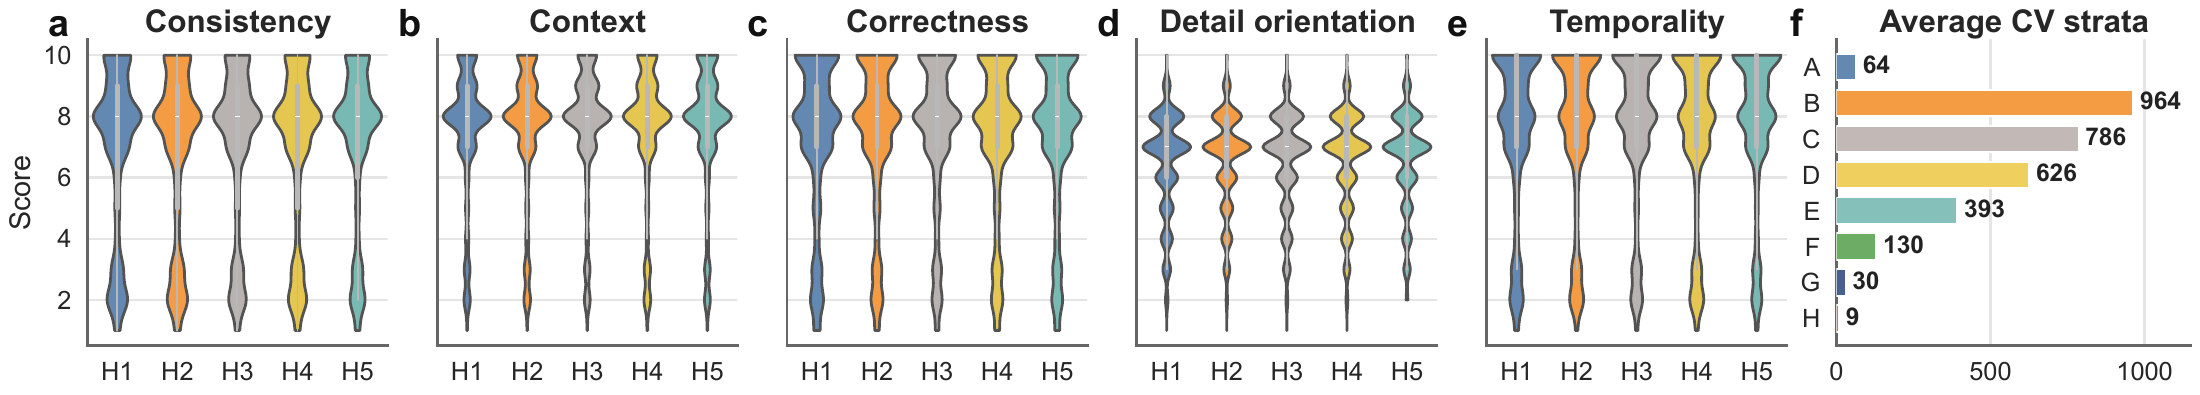
We measure annotation variation across five semantic dimensions—consistency, context, correctness, detail, and temporality—plus caption length. Their average coefficient of variation assigns videos to eight disagreement groups, A–H.
FIOVAhard comprises the 169 videos in Groups F–H, where human descriptions show the greatest disagreement.
Human annotation variability across the eight disagreement strata. Select image to enlarge.Compare dataset reference structures
Reference structures across datasets
Swipe or scroll horizontally to view all columns.
Adapted from manuscript Table I. Scale units and caption-aligned lengths follow the original sources.
Dataset
Reference structure
Scale
Average aligned length
Average text length
HowTo100M
ASR-generated
136M clips
≈4s
4.0 w
ACAV
A/V only
100M clips
10.0s
--
YT-Temporal-180M
ASR-generated
180M frames
--
--
HD-VILA-100M
ASR-generated
103M clips
13.4s
32.5 w
Panda-70M
LVLM-generated
70.8M clips
8.5s
13.2 w
MSVD
Multiple human refs.
1.97K clips
9.7s
8.7 w
LSMDC 2015
1 aligned ref.
118K clips
4.8s
9.7† w
MSR-VTT
≈20 human refs.
10K clips
≈15s
9.3† w
DiDeMo
Moment-level refs.
10.5K videos
6.9s
8.0 w
ActivityNet Captions
Event-level refs.
20K videos
36.0s
13.5 w
YouCook2
Step-level refs.
2K videos
19.6s
8.8 w
VATEX
10 EN + 10 ZH refs.
41.3K videos
≈10s
15.2 w
DREAM-1K
1 detailed ref.
1K clips
8.9s
59.3 w
AuroraCap (VDC)
1 reviewed ref.
1,027 videos
28.2s
500.9 w
FIOVA (Ours)
5 independent + UCG
3,002 videos
33.6s
61.4 w
ASR: automatic speech recognition; A/V: audio–visual; w: words. Aligned length follows the captioned moment, event, or step where applicable. VATEX text length refers to English captions; HowTo100M excludes stop words. MSVD statistics and DiDeMo mean lengths follow Panda-70M. † Calculated from aggregate statistics in the original papers. Full source references are listed in manuscript Table I.
Video, caption, and vocabulary distributions
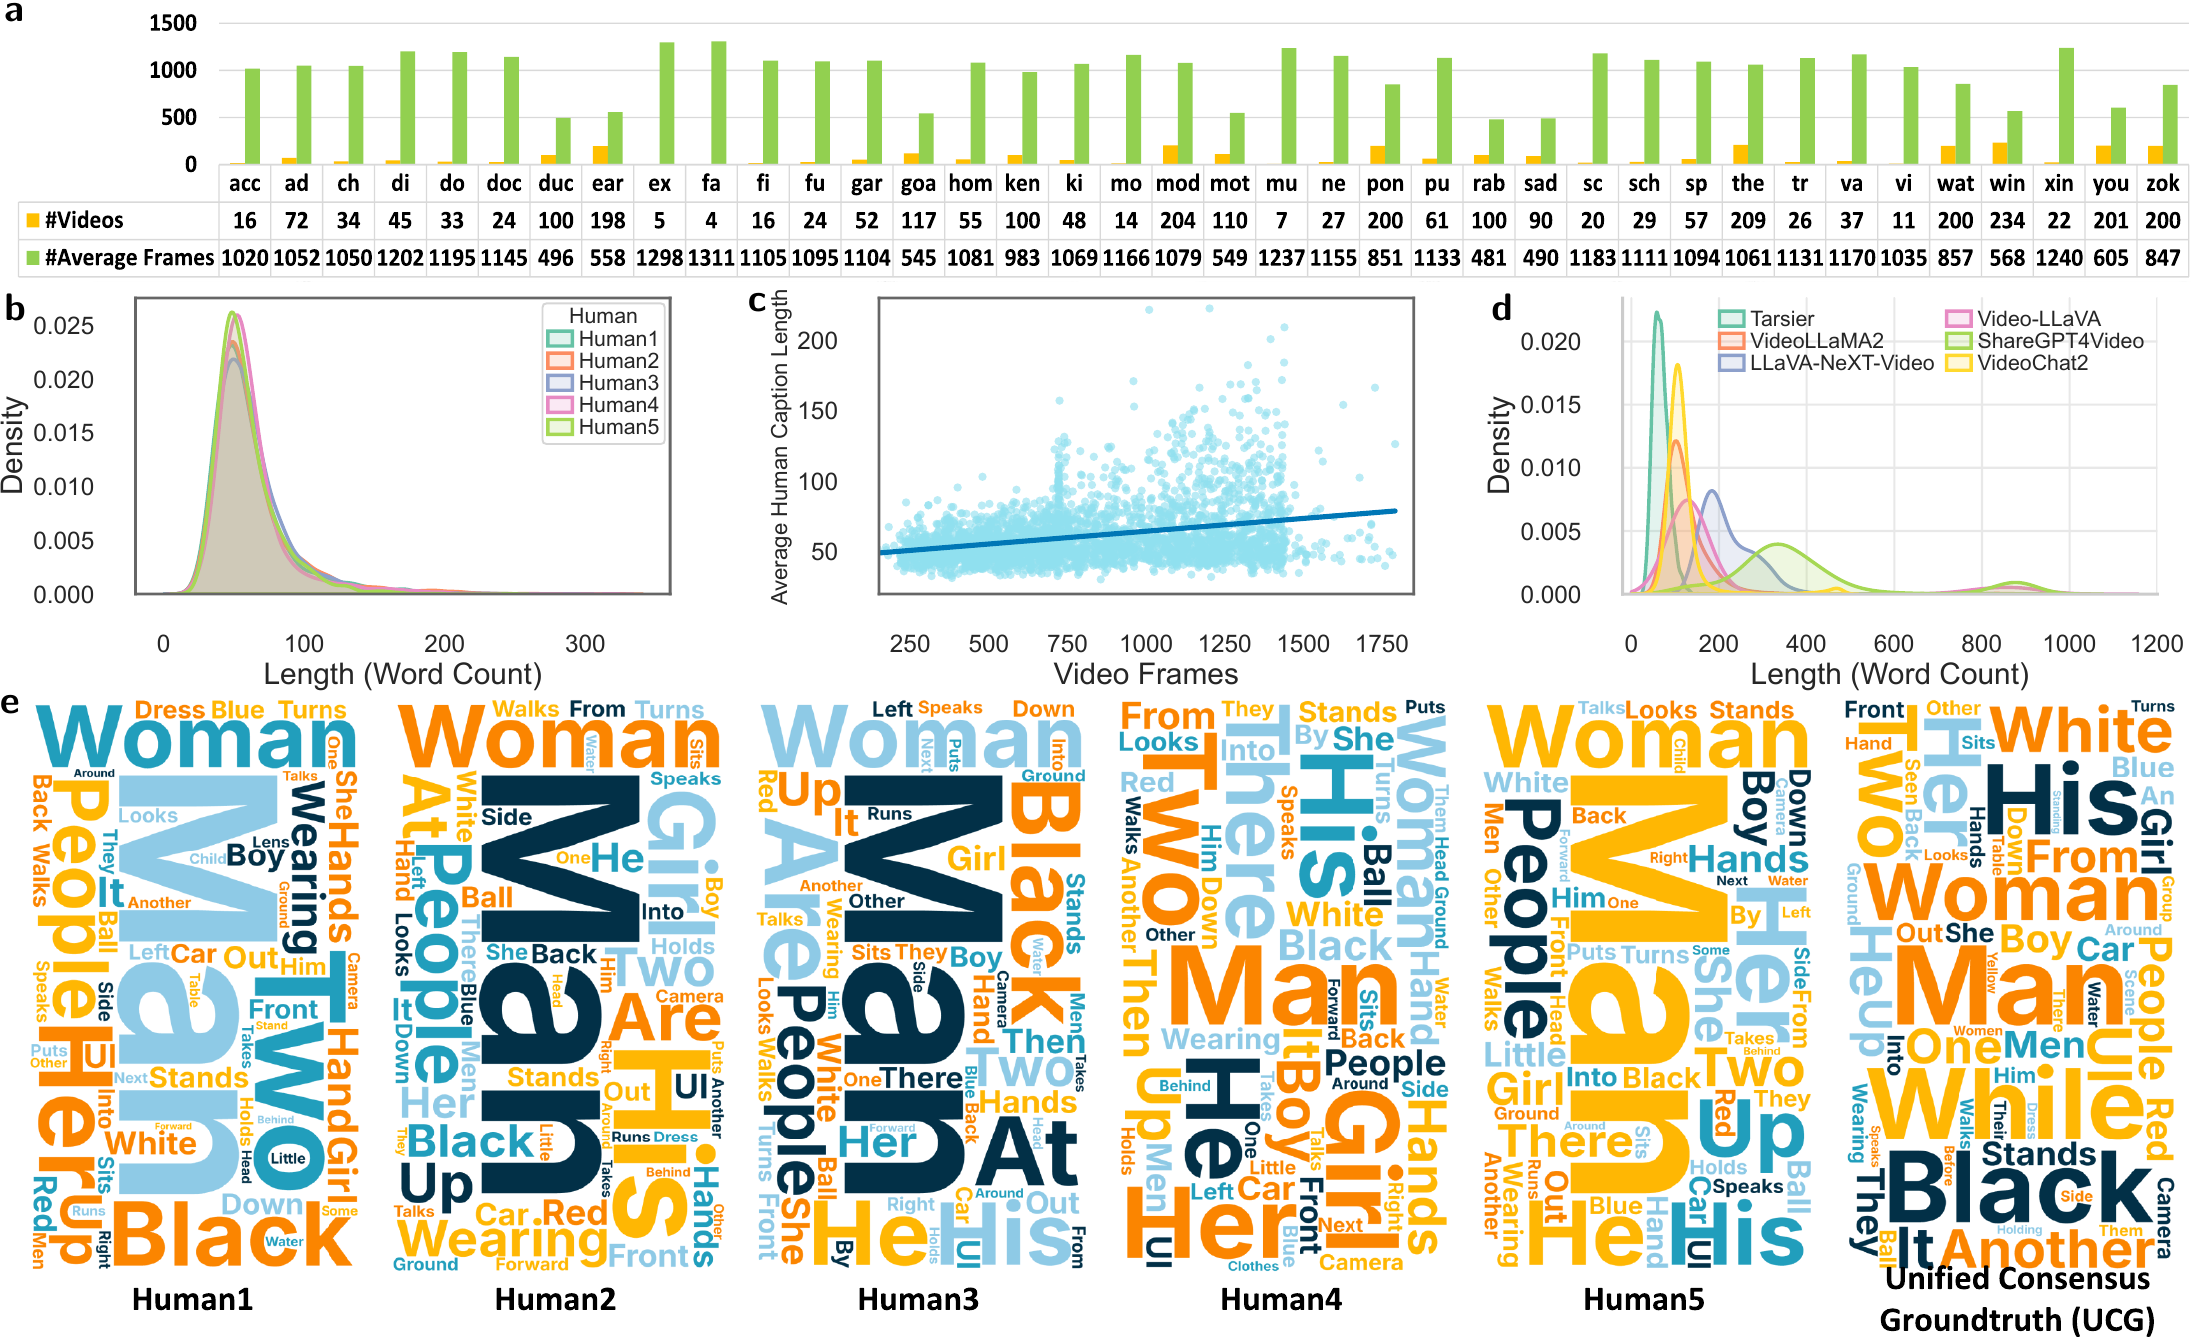
Dataset and response statistics: video length, human-caption granularity, caption length versus duration, baseline response lengths, and vocabulary across human captions and UCG. Select image to enlarge.
Human annotation reliability and disagreement strata
Score distributions across the five semantic dimensions and video counts across the eight fixed-width disagreement strata. Select image to enlarge.
Evaluation
From captions to event scores
A common captioning task
We evaluate six baseline LVLMs on the full benchmark and twelve models on FIOVAhard, using eight input frames for the main comparison.
Three complementary metric families
Lexical metrics: BLEU, METEOR, and GLEU compare wording with UCG.
AutoDQ: extracted events are matched with equal weight.
FIOVA-DQ: human descriptions guide event-importance weights, emphasizing events that matter more to the annotators.
Precision measures support for predicted events; Recall measures coverage of reference events. FIOVA-DQ weights both by event importance and combines them through F1.
Event extraction, human-guided weighting, and bidirectional support matching. Select image to enlarge.
Benchmark results
Full-benchmark results
Six baselines · 3,002 videos · 8 frames
Swipe or scroll horizontally to view all columns.
Manuscript Table III. Higher is better for each metric.
Model
Lexical
AutoDQ
FIOVA-DQ
BLEU
METEOR
GLEU
Precision
Recall
F1
Precision
Recall
F1
Tarsier
0.043
0.265
0.119
0.372
0.283
0.284
0.416
0.285
0.279
VideoLLaMA2
0.030
0.268
0.088
0.320
0.245
0.236
0.355
0.250
0.239
LLaVA-NeXT-Video
0.020
0.270
0.060
0.326
0.221
0.224
0.356
0.229
0.227
Video-LLaVA
0.027
0.257
0.077
0.291
0.208
0.199
0.320
0.216
0.198
ShareGPT4Video
0.010
0.218
0.034
0.269
0.201
0.185
0.286
0.203
0.174
VideoChat2
0.037
0.281
0.098
0.344
0.237
0.239
0.379
0.243
0.241
Scores are averaged across videos; F1 is computed per video before averaging.
Tarsier has the highest FIOVA-DQ Precision, Recall, and F1 among the six baselines. VideoChat2 follows in FIOVA-DQ F1. The lexical metrics distinguish other aspects of the captions: VideoChat2 leads in METEOR, while Tarsier leads in BLEU and GLEU.
Agreement with human preferences
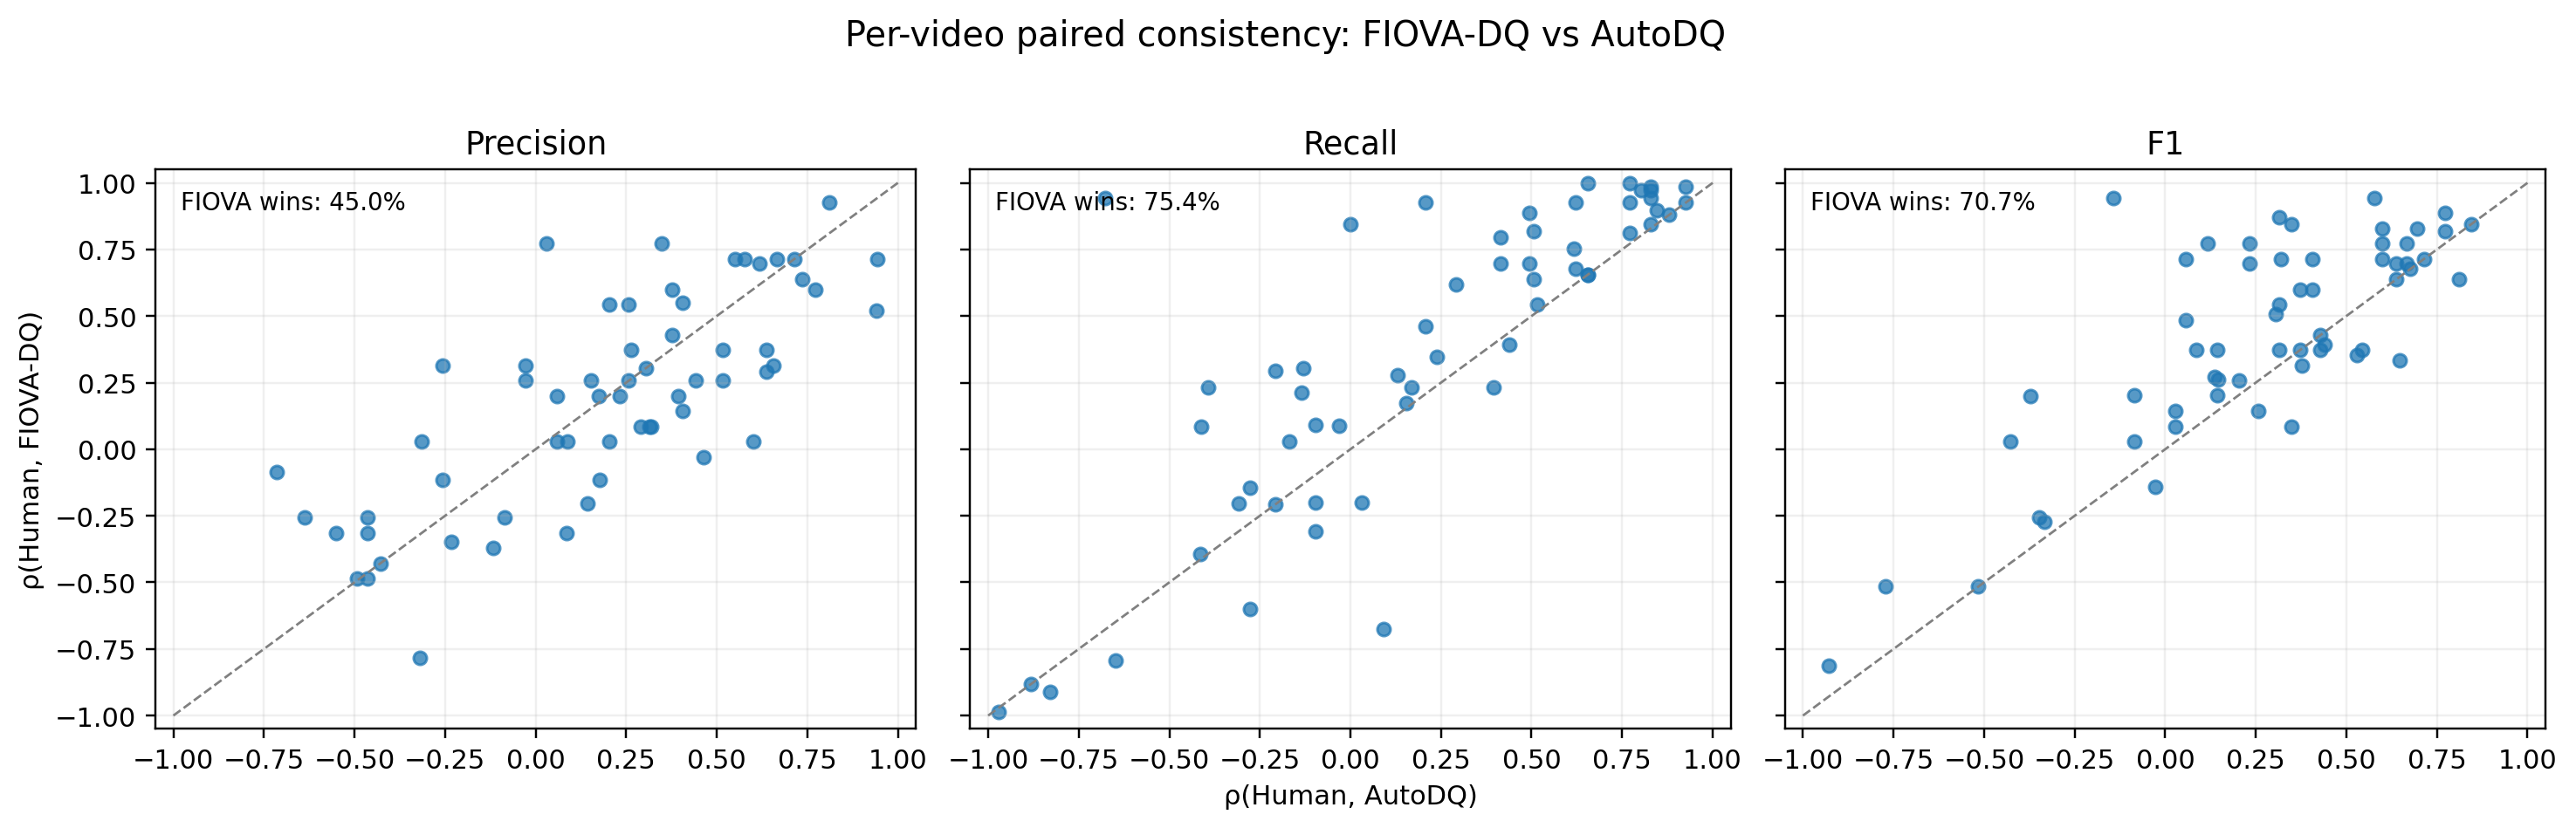
Forty participants rank six model captions for each of 60 videos. Comparing metric rankings with the aggregate human ranking shows stronger agreement for FIOVA-DQ in Recall and F1; Precision-based agreement is similar between the two metrics.
Mean Spearman correlation with human rankings
Swipe or scroll horizontally to view all columns.
Manuscript Table IV and Appendix E-B.
Metric
Precision
Recall
F1
AutoDQ
0.198
0.215
0.264
FIOVA-DQ
0.188
0.371
0.426
See Appendix E-B for the human-ranking protocol and paired analyses.
Agreement with human rankings, video by video
Each point compares the two metrics on the same video. Points above the diagonal indicate stronger human alignment for FIOVA-DQ. Select image to enlarge.
Analysis
How model behavior changes with human disagreement
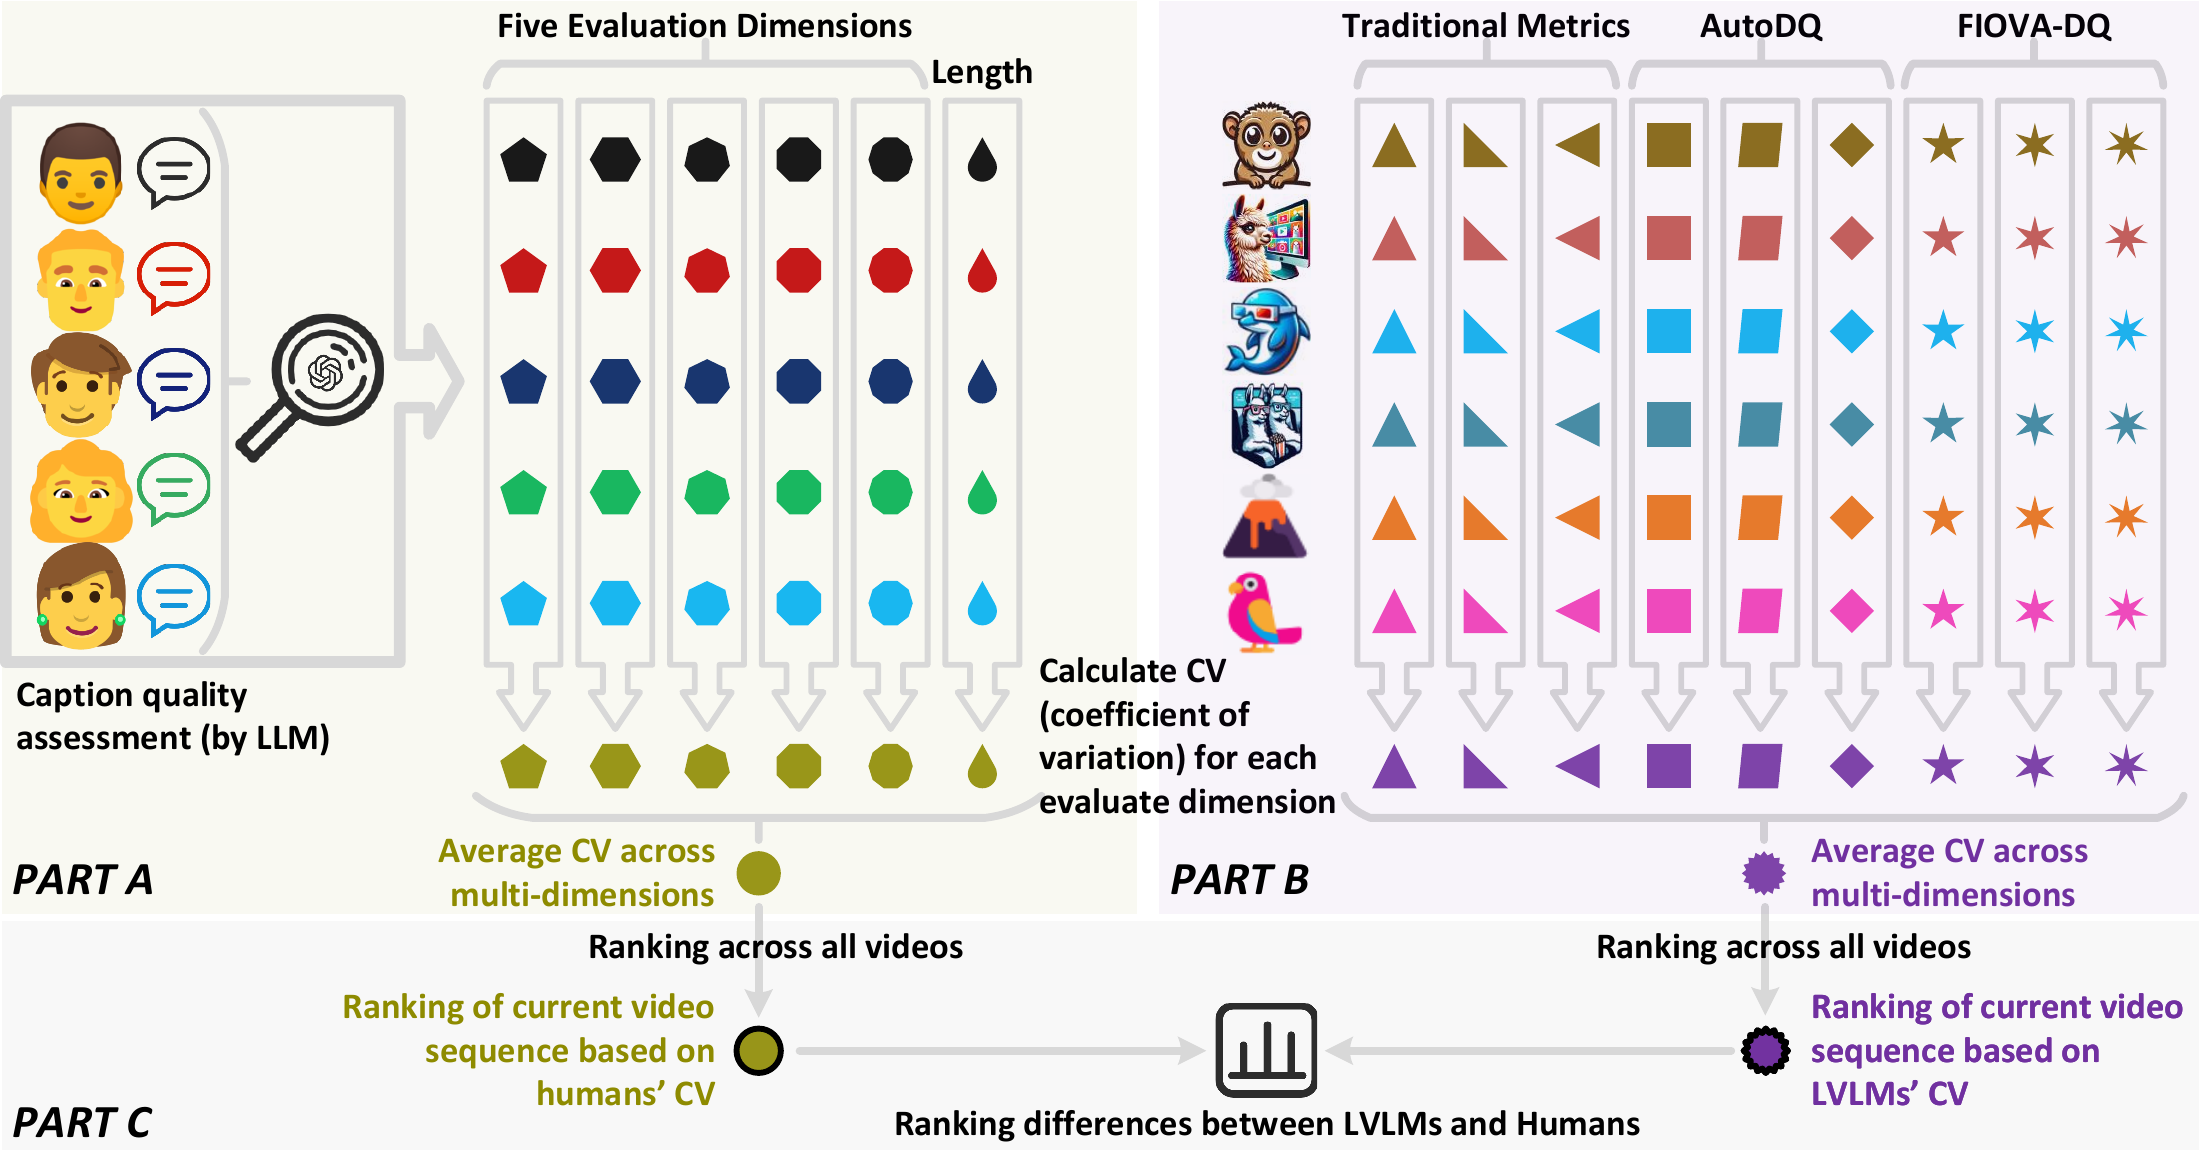
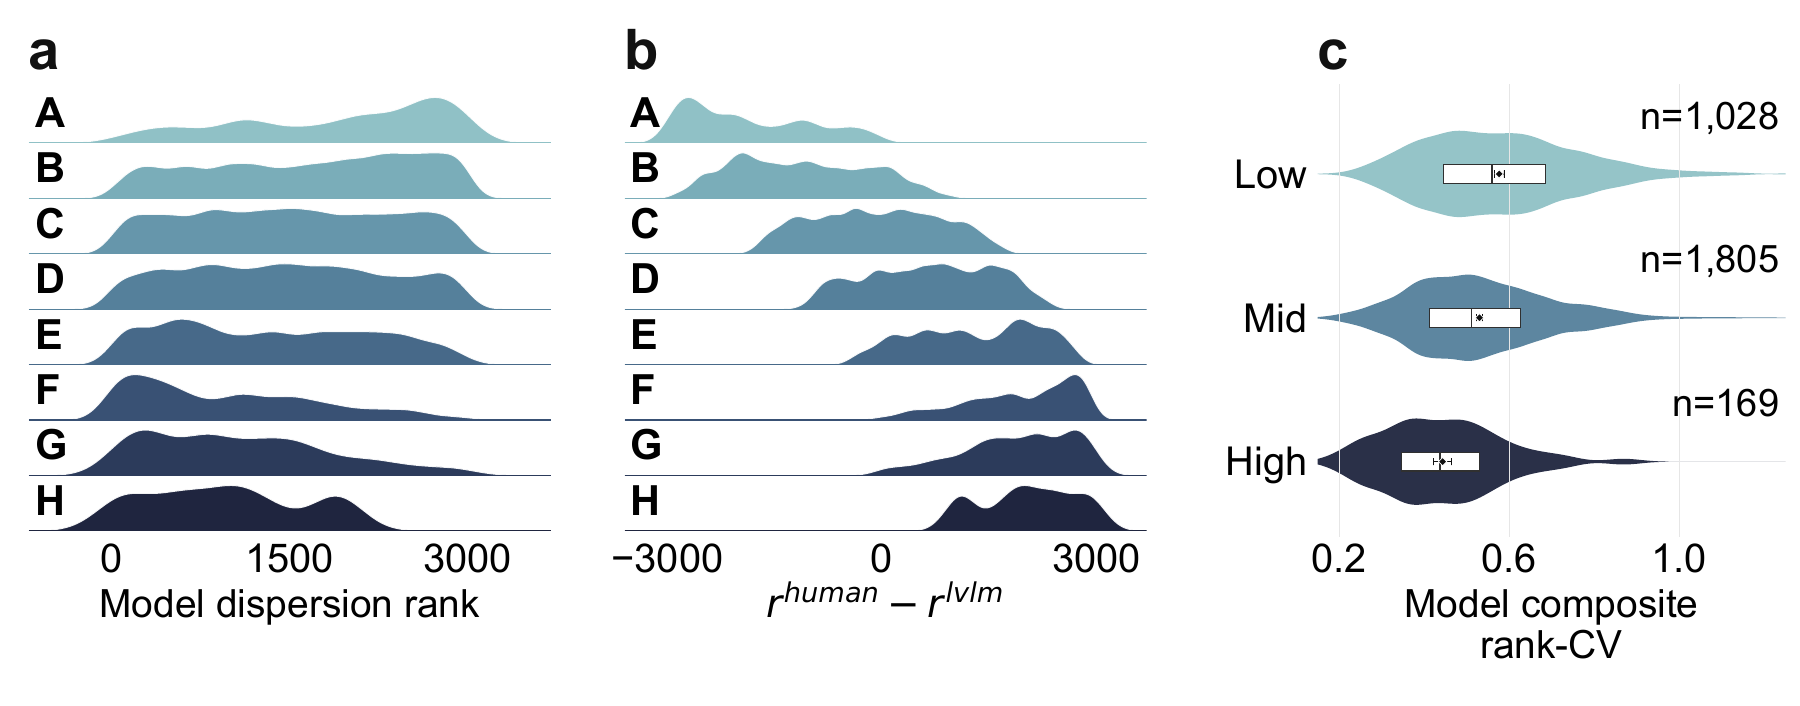
Batch-Ranking ranks videos separately for each model and metric, then compares the same video’s rank positions across models. Averaging their relative dispersion across nine metrics reveals how model behavior varies with human disagreement.
Batch-Ranking: human disagreement, model-specific video ranks, and their comparison. Select image to enlarge.
The complexity compression effect
Greater human disagreement is associated with lower model-side relative rank dispersion (Spearman ρ = −0.179). Mean rank-CV is 23.0% lower in High (F–H) than in Low (A–B).
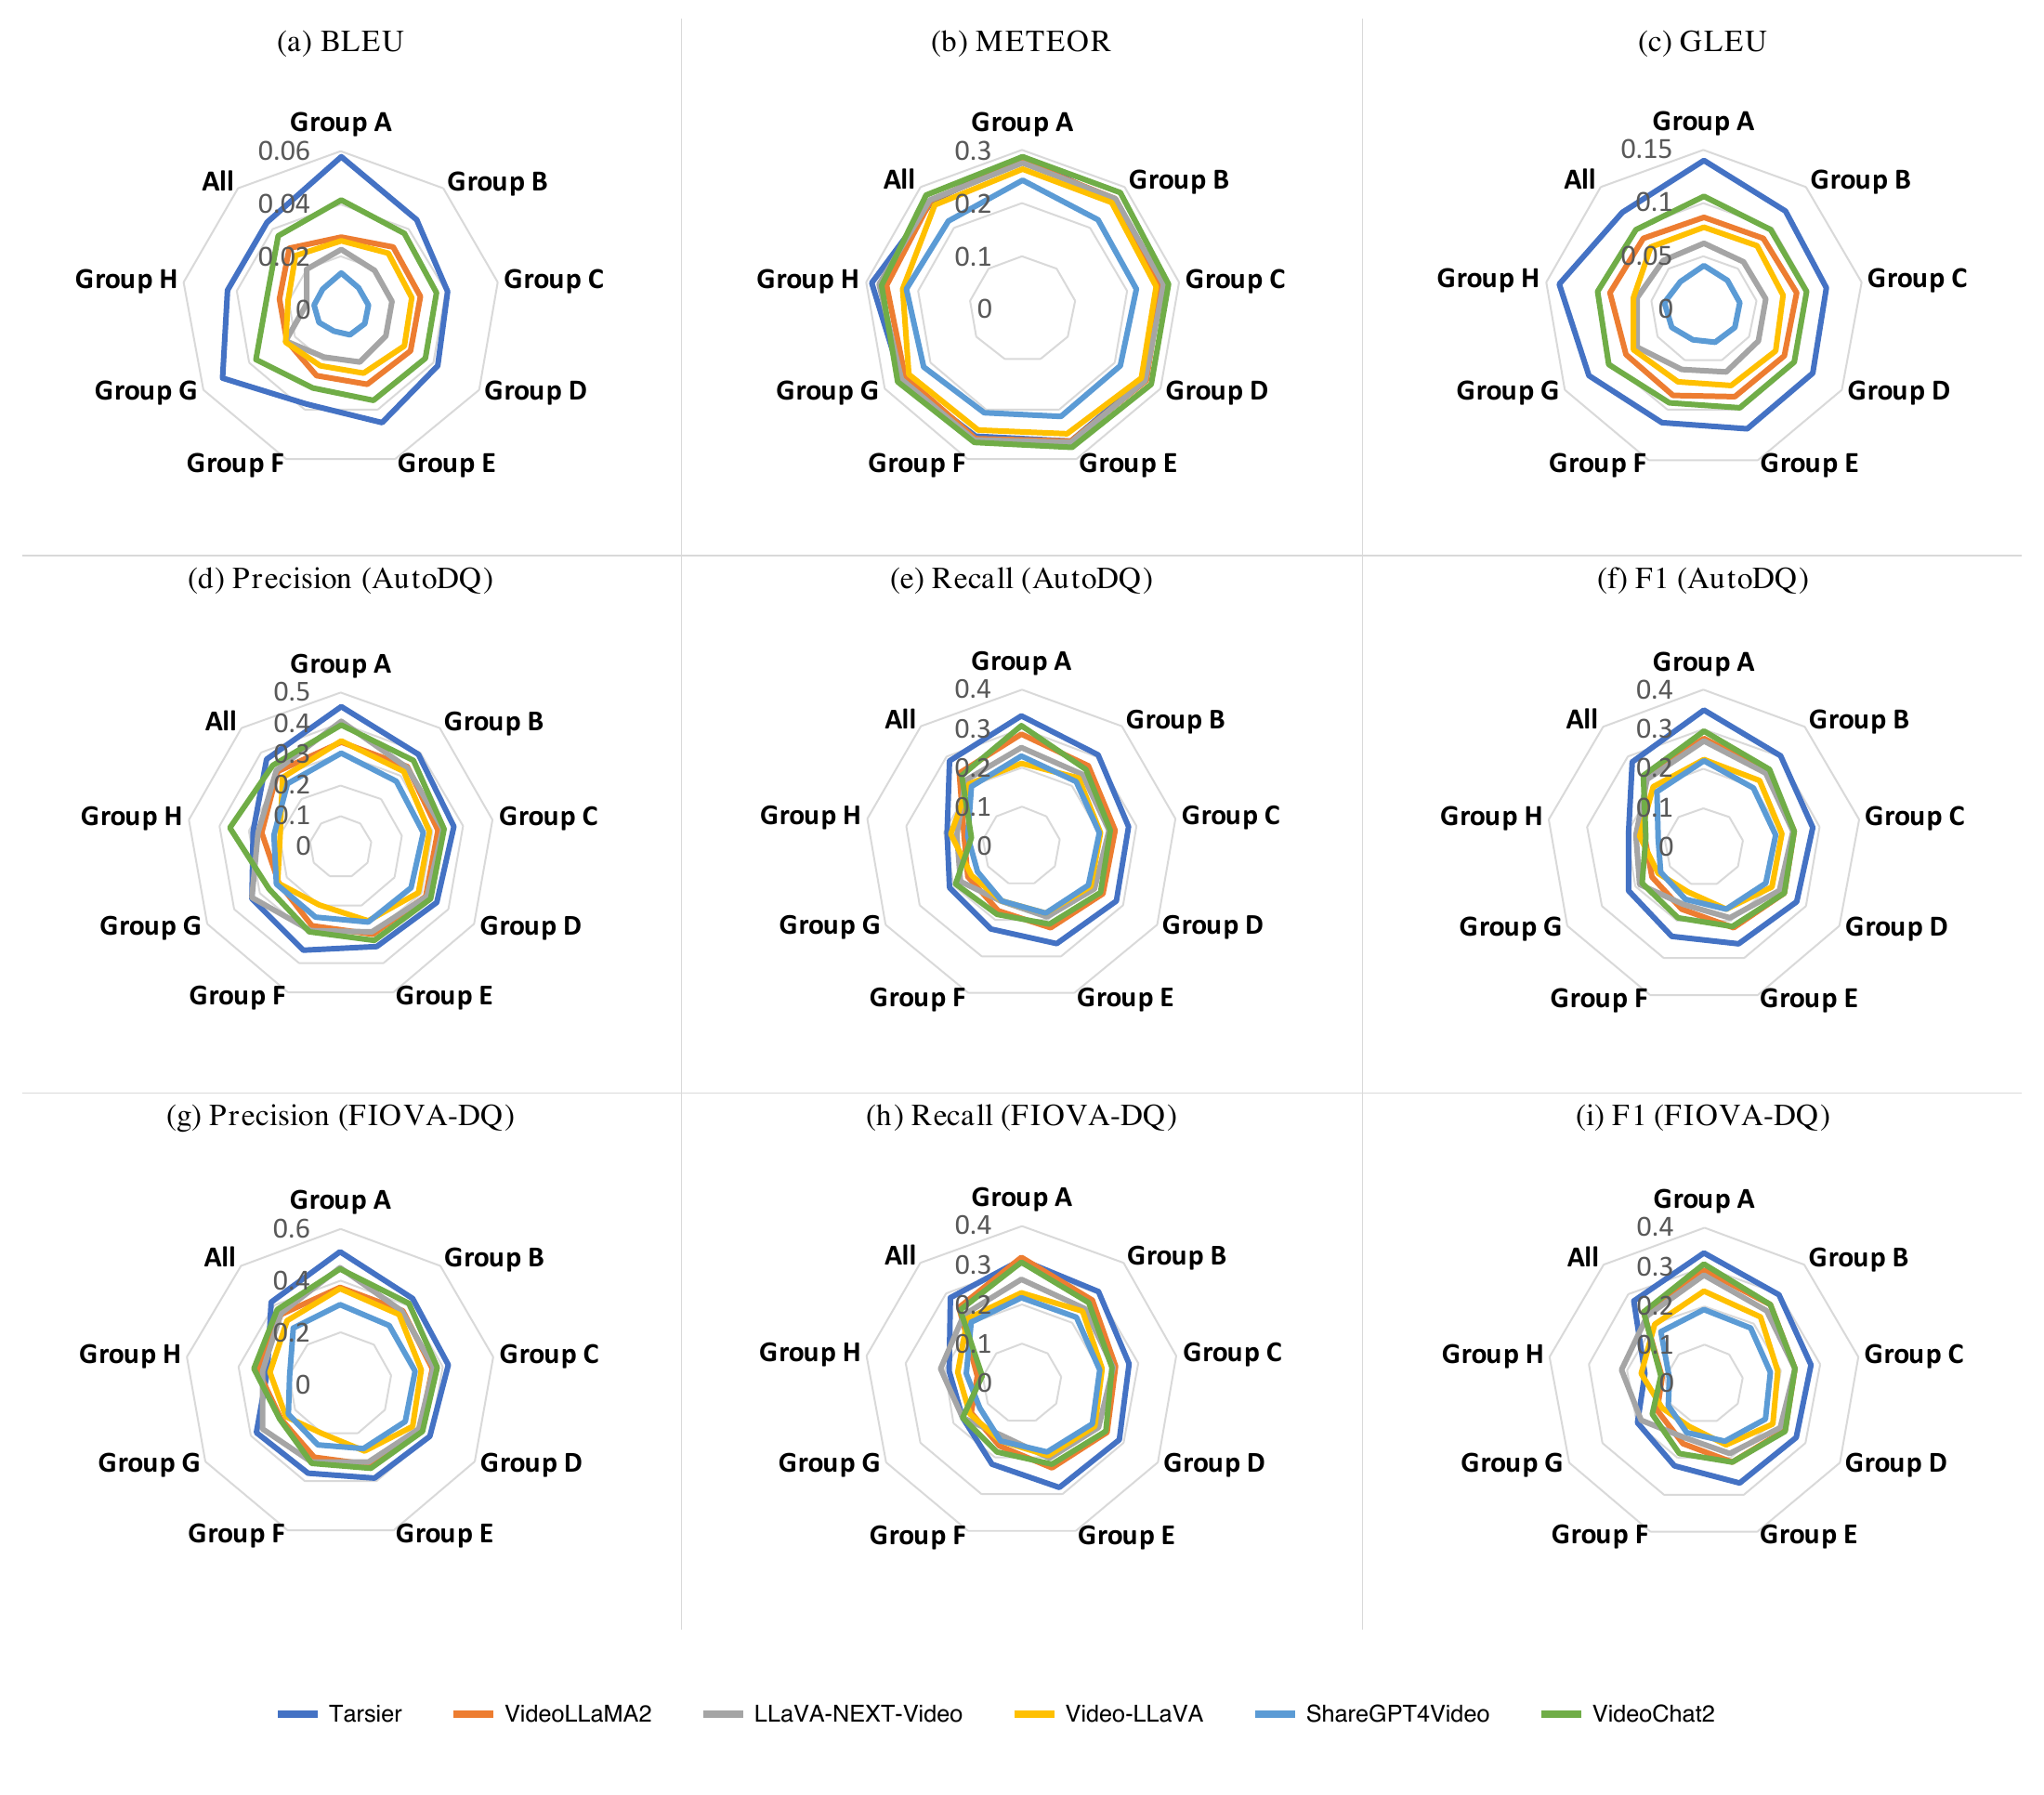
All six baselines also have lower event Precision, Recall, and F1 in Group H than in Group A, connecting reduced rank dispersion with reduced event support and coverage.
Relative model dispersion, human–model rank differences, and pooled Low/Mid/High comparisons. Select image to enlarge.Caption length provides another view
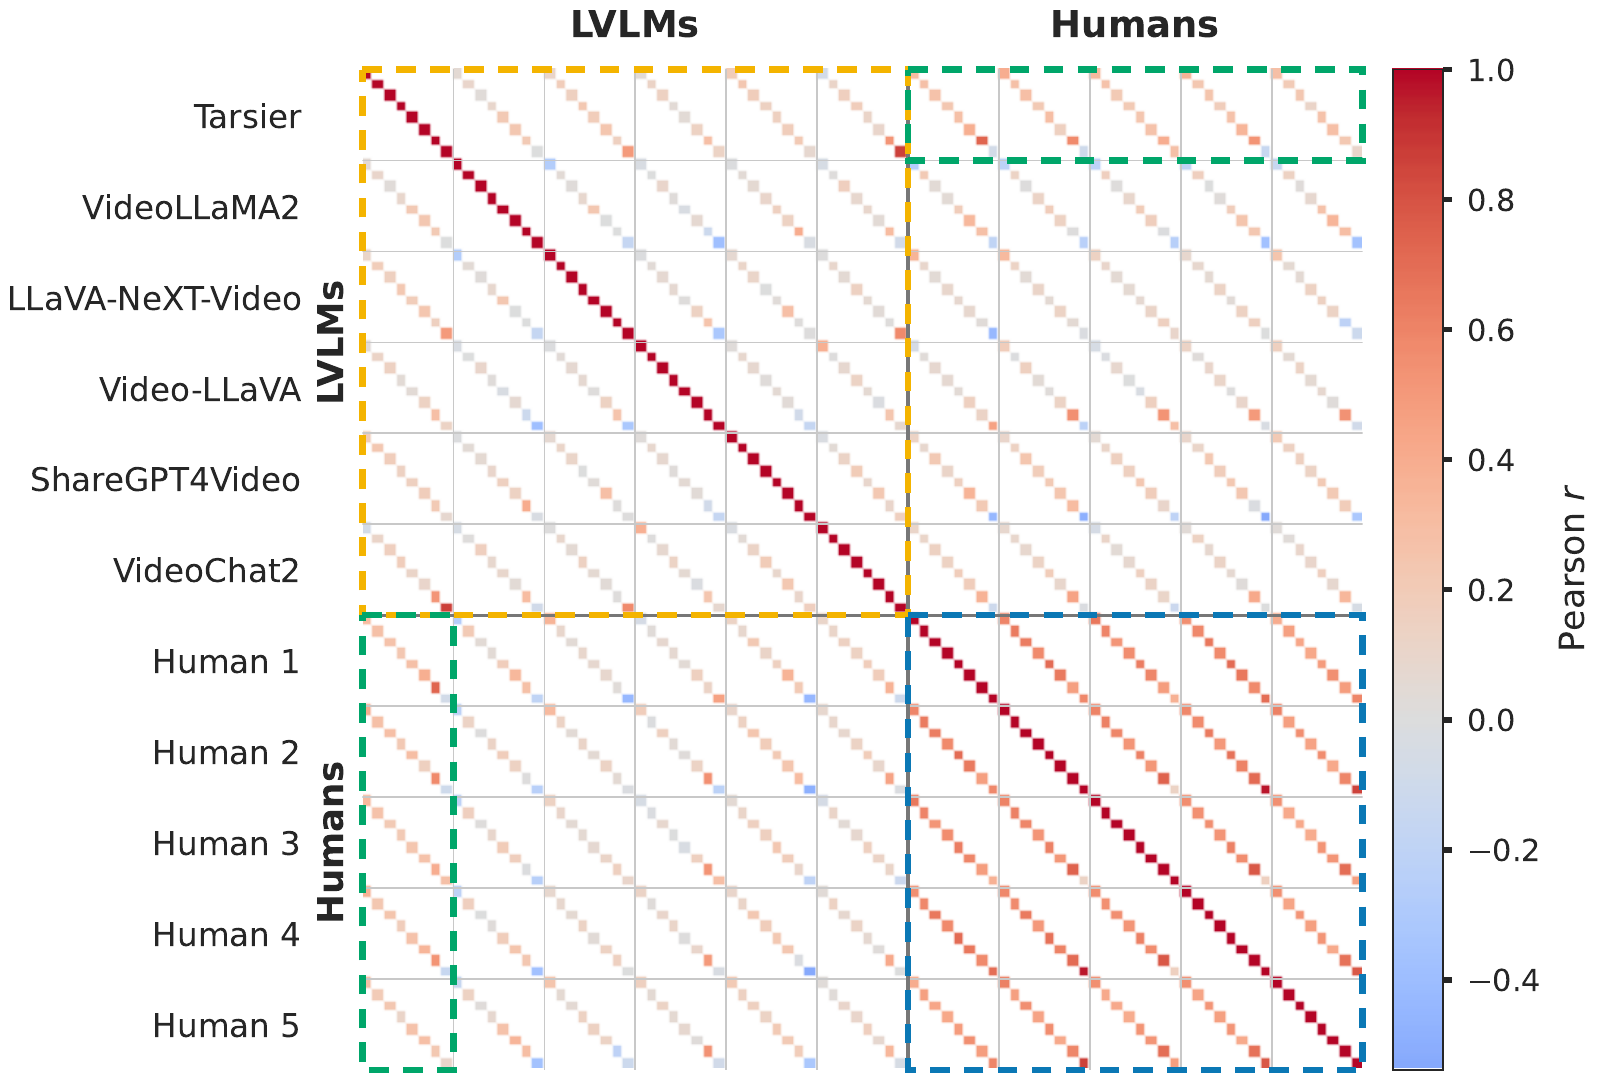
Description-length correlations across videos, computed separately within Groups A–H. Human1–Human5 are caption slots. Select image to enlarge.
Model scores across the full dataset and Groups A–H
Six baseline models across the full benchmark and its disagreement strata. Precision, Recall, and F1 are lower in Group H than Group A for all six models, with local reversals in intermediate groups. Select image to enlarge.
Stress test
Twelve models on FIOVAhard
High-disagreement subset · 169 videos · 8 frames
Swipe or scroll horizontally to view all columns.
Manuscript Table V. The six additional models are shown separately from the six full-benchmark baselines.
Model
Lexical
AutoDQ
FIOVA-DQ
BLEU
METEOR
GLEU
Precision
Recall
F1
Precision
Recall
F1
Six full-benchmark baselines
Tarsier
0.040
0.258
0.116
0.348
0.222
0.236
0.364
0.210
0.214
VideoLLaMA2
0.026
0.259
0.085
0.265
0.171
0.165
0.294
0.164
0.155
LLaVA-NeXT-Video
0.020
0.264
0.062
0.294
0.156
0.163
0.323
0.152
0.157
Video-LLaVA
0.023
0.242
0.072
0.204
0.151
0.125
0.216
0.156
0.118
ShareGPT4Video
0.009
0.210
0.031
0.241
0.146
0.137
0.244
0.150
0.127
VideoChat2
0.032
0.268
0.095
0.293
0.185
0.187
0.317
0.180
0.179
Six additional models
Tarsier2
0.048
0.272
0.128
0.299
0.225
0.212
0.389
0.273
0.247
InternVL-2.5
0.015
0.245
0.073
0.252
0.203
0.185
0.311
0.240
0.207
InternVL-3
0.016
0.248
0.075
0.224
0.204
0.175
0.276
0.221
0.181
Qwen2.5-VL
0.017
0.250
0.076
0.309
0.187
0.187
0.366
0.213
0.199
GPT-4o
0.023
0.262
0.087
0.296
0.243
0.231
0.390
0.296
0.268
Gemini-2.5-Flash
0.021
0.259
0.082
0.292
0.245
0.227
0.369
0.296
0.270
All six baselines have lower FIOVA-DQ Precision, Recall, and F1 on FIOVAhard than on the full benchmark. Tarsier's F1 decreases from 0.279 to 0.214.
Gemini-2.5-Flash and GPT-4o lead in FIOVA-DQ F1 (0.270 and 0.268), followed by Tarsier2 (0.247).
Does adding frames help?
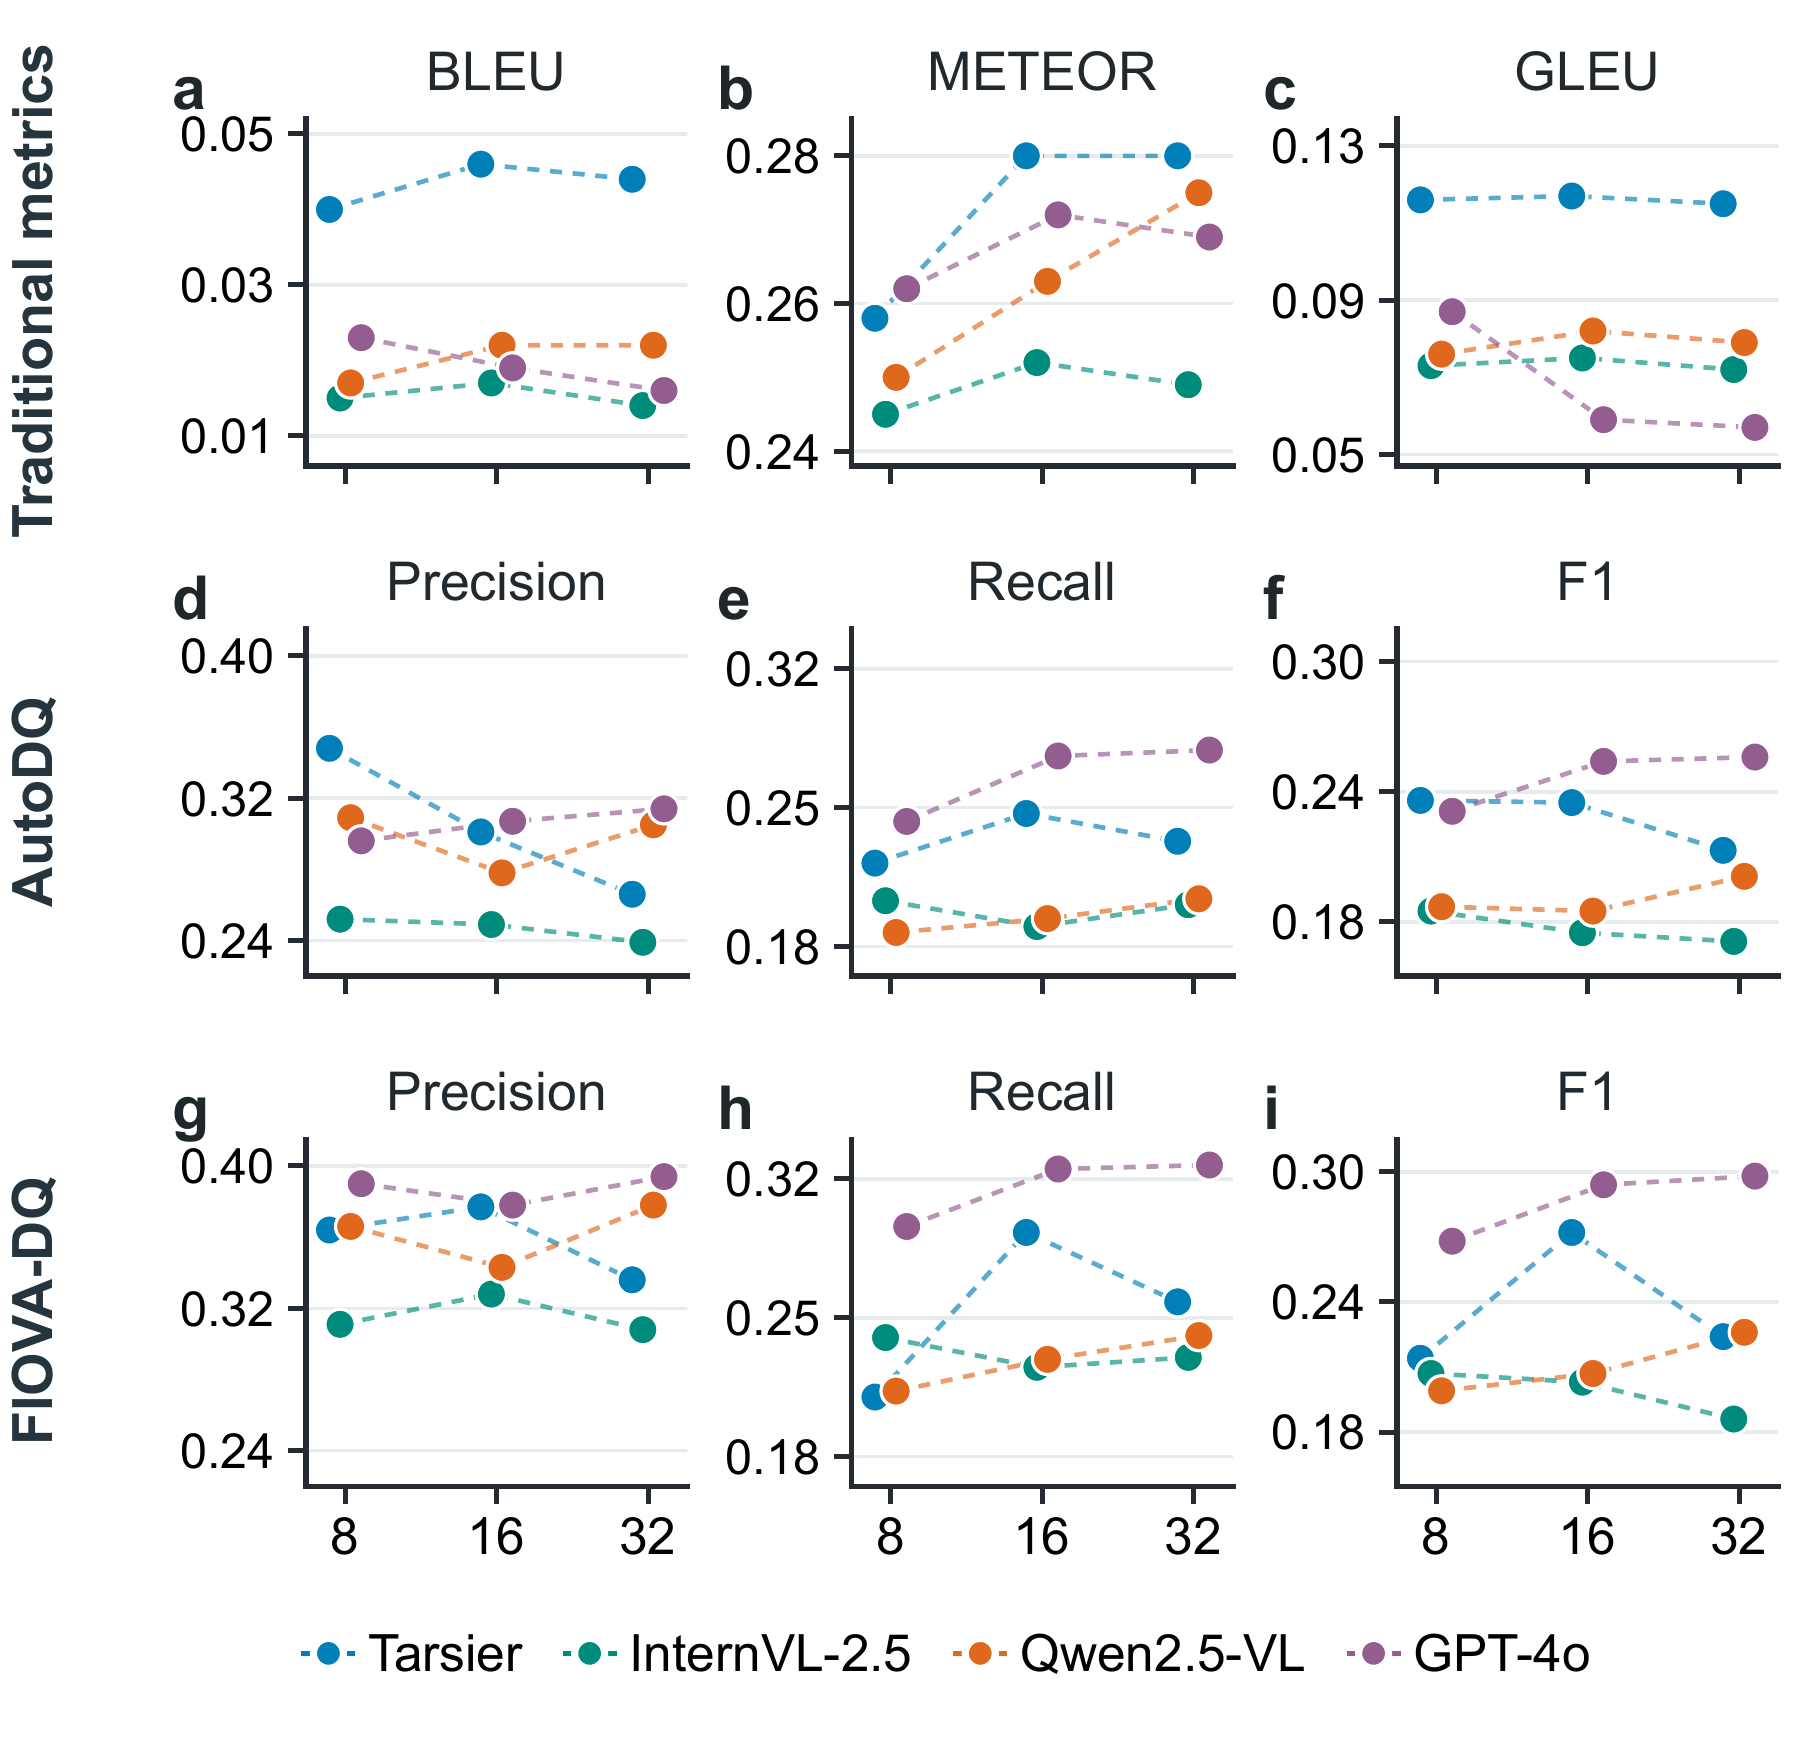
For FIOVA-DQ F1, GPT-4o and Qwen2.5-VL improve as the frame count increases. Tarsier peaks at 16 frames and then declines; InternVL-2.5 declines across the tested frame counts. The benefit depends on both the model and metric.
Eight-, sixteen-, and thirty-two-frame comparisons for four models across nine metrics. Select image to enlarge.Complete frame-count results
Four models · three frame counts
Swipe or scroll horizontally to view all columns.
Appendix Table A6. Mean scores across FIOVAhard videos.
Model
Frames
Lexical
AutoDQ
FIOVA-DQ
BLEU
METEOR
GLEU
Precision
Recall
F1
Precision
Recall
F1
Tarsier
8
0.040
0.258
0.116
0.348
0.222
0.236
0.364
0.210
0.214
Tarsier
16
0.046
0.280
0.117
0.301
0.247
0.235
0.377
0.293
0.272
Tarsier
32
0.044
0.280
0.115
0.266
0.233
0.213
0.336
0.258
0.224
InternVL-2.5
8
0.015
0.245
0.073
0.252
0.203
0.185
0.311
0.240
0.207
InternVL-2.5
16
0.017
0.252
0.075
0.249
0.190
0.175
0.328
0.225
0.203
InternVL-2.5
32
0.014
0.249
0.072
0.239
0.201
0.171
0.308
0.230
0.186
Qwen2.5-VL
8
0.017
0.250
0.076
0.309
0.187
0.187
0.366
0.213
0.199
Qwen2.5-VL
16
0.022
0.263
0.082
0.278
0.194
0.185
0.343
0.229
0.207
Qwen2.5-VL
32
0.022
0.275
0.079
0.305
0.204
0.201
0.378
0.241
0.226
GPT-4o
8
0.023
0.262
0.087
0.296
0.243
0.231
0.390
0.296
0.268
GPT-4o
16
0.019
0.272
0.059
0.307
0.276
0.254
0.378
0.325
0.294
GPT-4o
32
0.016
0.269
0.057
0.314
0.279
0.256
0.394
0.327
0.298
Dataset demo
One video, five descriptions, one consensus
Watch a video, compare five independent human descriptions, and explore their unified consensus reference.
A boy and his bicycle
Five independent human descriptions
Human 1
A little gray boy is riding a bike. After a distance, the bike suddenly falls. The boy comes down from the bike, goes to the side, lies on the ground, pretending to fall. After a while, He reachs out his hand.
Human 2
A child sits on a bicycle seat to take it away. He releases his hand, and the bike turns over the right. He takes out his right leg and walks a few steps and falls to the ground. Then he stretches out his right hand pointing to the lens.
Human 3
A boy on the road is riding a small two-wheeled car, after driving a distance the child stops, the car falls to the ground, the boy comes down from the car, he lies on the road. The little boy lying on the floor strokes his hand and cries.
Human 4
A child wearing a hat is riding on a baby carriage forward, and then the car falls, the child stands for a while and falls off when he crosses his leg out from the car. The child is lying on the ground and then pointing to the camera by a finger.
Human 5
During the day, a little boy wearing a helmet is riding a bike without pedals,using feet to support forward. The boy release his hand, the bike tilted down under the boy. The boy stands and looks down at the bike. The boy crosses the car and goes to the side and falls to the ground. The boy smiles and reaches out his hand.
Unified Consensus Groundtruth (UCG)
A young boy is riding a bike down a road. As he rides, the bike suddenly falls over. The boy then gets off the bike, lies on the ground, and pretends to fall. After a moment, the boy smiles and reaches out his hand.
A baseball game and its spectators
Five independent human descriptions
Human 1
Three men are standing on the sidelines and watching the game. A white dress man throws the ball, and another gray dress man swings the bat. He does not hit the ball, and the bat flies out.Another gray dress man receives the bat on the sidelines. A green dress woman stands up and kisses the gray dress man. A gray dress man comes over to talk with the green dress woman. The video is repeatedly played from different angles.
Human 2
Several red dress men stand on the sidelines of the baseball field. A white dress athletes in the middle of the field pitches the ball,and another white dress player waves the bat. And the bat flies out. And he lifts his arms to look far away. A gray dress man stands in the auditorium.He smiles and holds a bat.The woman next to him stands up and kisses his cheek. A black dress man comes from the back row,and the woman turns back to talk with him. The lens replays the scene of bat flying out. The bat is caught by the gray dress man in the auditorium. The scene of catching the bat is replayed in slow motion. The whole process is replayed again.
Human 3
There are several men stand outside the ball park. There are several players in the ball park playing baseball. After a player has thrown the ball, the opposing player hits the baseball with bat and throws the bat away.Outside the ball park, a woman kisses the man smiling and standing with the bat in his hand.A man comes from behind and talks something to a woman. The lens replays the scene that the player throws out the bat and the man outside the pitch catches the bat.
Human 4
Three men wearing a red hat watches the ball on the sidelines. An athlete throws a ball on the ball part, the opposing players hits the ball and throws the bat to the audience. The bat is received by a man wearing short-sleeves. A woman next to him kisses the short-sleeved man. A man wearing a hat comes next to the woman and talks to her. And then the video just now is played in a slow motion.
Human 5
During the day, several men wearing red hats stand on the sidelines of the ball park. On the pitch, the pitcher throws the ball and the baseball player hits the ball with bat. The bat is threw out. The players watch the bat flying out. In the auditorium, a man holds a bat,and a woman next to him kisses his cheek. The people around applaud. The scene of the bat being threw out and the man catching the bat is replayed in a slow motion.
Unified Consensus Groundtruth (UCG)
Several men in red hats stand on the sidelines of a baseball game, watching as the pitcher throws the ball and the batter hits it, sending the bat flying. In the stands, a man catches the bat thrown from the field, while a woman kisses him on the cheek. Another man approaches the woman and appears to engage in conversation. The video clip is replayed multiple times, showing the action from different angles and in slow motion.
Reading, dancing, and changing scenes
Five independent human descriptions
Human 1
A woman wearing a small glasses is reading books. A woman wearing a big glasses is looking forward. A man sitting beside a lot of books and holding a book looks at the front. The woman wearing big glasses lies on the ground. A group of cranes walk by, a man and a woman dancing behind. A woman in pink walks, a man and a woman dancing behind. A black woman lies down and reads, a red dress woman sitting in a chair looks at the right. The woman with big glasses waves around the crane. A man wearing glasses is reading. The pink dress woman is walking through, the man wearing glasses is reading, the black woman is lying on a black and white shirt and reading. A man wearing a hat dances and walks through the black man upside down. A woman is lying next to a group of cranes. A woman steps on the book and walks. The woman in pink is dancing and walking through, a crane also comes.
Human 2
The lens sweeps a lady from top to bottom, and then there appears a woman with curly hair. A man is wearing a suit, the man lying down is looking at her. Lens switch, the lady is lying on the floor, a group of white flamingos walk by, someone next to them is dancing. A man and a woman push around, the first lady appears lying down and reading, the man in suit also wears glasses reading, the curly hair women and flamingos are dancing, someone next to them stretches his leg doing exercise.
Human 3
In a yard, a black-skinned woman is carrying a bag in the hands and reading a book, another long-haired woman is staring at the camera. A woman wearing a suit is lying on the stool, holding A book and looks at the lens, the long hair woman is lying on the carpet. A group of birds walk through the hall, a red dress man pushes a blonde woman away, the black skin woman next to him sitting to the side reads, another woman with black skin is lying down and reading. A woman wearing a red hat is sitting to the side, the long hair woman shakes hands, a woman in suit wears glasses, another woman wearing a striped shirt lies next to the carpet. The man in red keeps beating, A woman lying on the table raises her legs, the long hair woman is lying on the carpet, a pink dress woman is shaking the body and walking through.
Human 4
A woman standing next to some leaves. A woman is lying on the ground. Some geese are walking. A man and a woman are talking. A man is reading a book. A woman is sitting in a chair. A woman is waving her hands. A man is wearing glasses. Several people are lying on the ground. A man is leaning up and a man is walking by his side.
Human 5
A woman carrying a bag is standing and reading. A woman wearing glasses looks at the camera. A person holding a book looks at the woman. The woman wearing glasses is lying on the ground. Several people are dancing, a person is lying down and reading, a person is sitting on a chair. A man is waving his hands. The reading people wears the glasses. A man jumps forward and looks at another person who stands on the stool. The women with glasses is lying on the ground. A person steps on the book. Everyone does their own thing.
Unified Consensus Groundtruth (UCG)
A diverse group of individuals are shown in a video clip. A woman with small glasses is reading a book, while a woman with big glasses looks for-ward. A man surrounded by books holds a book and gazes ahead. The woman with big glasses lies on the ground as a group of cranes walk by, with a man and woman dancing behind. Another scene shows a woman in pink walking, with a man and woman dancing behind. A black woman is seen lying down and reading, while a woman in a red dress sits in a chair looking to the right. The woman with big glasses waves around a crane. A man wearing glasses reads a book. The woman in pink continues walking, while the man wearing glasses reads, and the black woman lies on a black and white shirt reading. A man wearing a hat dances and walks as another man is upside down. A woman is lying next to a group of cranes, and another woman steps on a book as she walks. The woman in pink dances and walks, and a crane is also present. The video also shows a scene where a lady is swept from top to bottom, followed by a woman with curly hair. A man in a suit is looking at her, while someone else is lying down. The lens switches to the lady lying on the floor, as a group of white flamingos walk by and someone dances. A man and woman push each other, and the initial lady appears lying down and reading, along with the man in the suit reading. The curly-haired woman and flamingos dance as someone exercises. In another part of the video, a black-skinned woman is seen carrying a bag and reading a book next to a long-haired woman looking at the camera. A woman in a suit lies on a stool and holds a book, while a group of birds walk through the hall. A man in a red dress pushes a blonde woman, with the black-skinned woman reading nearby. Another black-skinned woman is lying down and reading, while a woman in a red hat sits to the side, and a woman with long hair shakes hands. A woman in a suit with glasses sits next to a woman in a striped shirt lying down. The man in red keeps moving, a woman lying on a table raises her legs, the long-haired woman is on the ground, and another woman in a pink dress is shaking and walking. In another scene, a woman stands next to some leaves, while a woman lies on the ground and geese are walking by. A man and woman talk, a man reads a book, a woman sits in a chair, and a woman waves her hands. The man in glasses is reading, several people lie down, a man leans up, and a man walks by. Another scene shows a woman carrying a bag and reading, a woman with glasses looking at the camera, a person holding a book gazing at a woman, and the woman with glasses lying on the ground. Several people dance, another person reads while lying down, one person sits on a chair, and a man waves his hands. The readers wear glasses as a man jumps forward to look at another person standing on a stool. The woman with glasses is still on the ground, while another person steps on a book. Each individual is captured doing their own activity in the video clip.
A party across several scenes
Five independent human descriptions
Human 1
A woman is sitting, and several people are sitting together. The table is covered with bread. The other three are standing. The woman looks at the camera. At a party, the woman laughs.
Human 2
A woman holding a cup sits on the steps. Several people are sticking papers to the balloon. There are food on the table. A cake in one man’s hand falls to the ground. At another party, the woman holds a windmill in her hand. There are food on the table. The children run around.
Human 3
A woman dressed in white holding a cup sitting. She looks to somewhere else.There is a dining table next to her.She is holding a corn and eating. She gives some food to the girls then she smiles.
Human 4
A black woman sits on the steps, bread is putted on the table, a black man throws the hamburger on the ground. Many people play together, there are corn and burger on the table, some little girls run to her and talk with her.
Human 5
A woman is sitting in a seat with a glass of water. A man squeezed the tomato sauce on the cake and the cake falls to the ground. Woman is holding a windmill. A group of people are dining. There are a variety of foods on the table. A group of children run around on the lawn.
Unified Consensus Groundtruth (UCG)
A woman is sitting at a party, looking at the camera and laughing. Several people are sitting together at a table covered with bread while others are standing. Meanwhile, a cake falls to the ground as a man tries to stick papers to a balloon. The woman then holds a windmill and interacts with children running around. There are various foods on the table, including corn, burgers, and a tomato sauce squeezed on a cake.
A martial-arts demonstration
Five independent human descriptions
Human 1
man in white falls down to the ground and keeps speaking. His right leg is under the crotch of the man in black who is kneeling down. the right foot of the man in black is on the ground. man in white holds trousers of the man in black. the man wears black dress,the man 's right leg restores the original action. Man in white is on the right side of his body, he puts his left foot on his right foot, left hand holds the left shoulder of the man in black , then he uses his left leg to draw a circle and pulls the man in black to the left rear. His left hand seizes the left arm of the man in black,he raises his right beg to turn the man in black over. His right hand presses the left arm of the man in black to his back, conversation is over.
Human 2
In a judo field, a man in black stands between the legs of the man in white and raises his arms,the man in white lies on the ground, the white man lies on the ground and speaks. He touches the shanks of the man in black and puts him on the ground. His legs clamps the thigh of the man in black, his left hand is on the left shoulder of the man in black, the man in black lies on him,the body of the man in white turns over, he throws the man in black down to the ground and hugs his arm.
Human 3
a man in white lies on the ground and talks, man in black kneels down in front of him. the man in black raises his leg and crosses with one leg of the man in white. man in white pulls the pants of the man in black, and pulls his legs down to the ground. Then the man in white lifts another leg to hit the chest of the man in black, and pushes his shoulders with his hands. After the white man stretching his legs twice, he raises his legs bypass the head of the man in black, with leveraging knocks down the man in black. After then, the man in white uses the leveraging again, turns over the man in black, he takes advantage of this opportunity and gets up, locks his arms. He releases the man in black.
Human 4
the man in white and the man in black perform to explain the action essentials. man in white lies on the ground, the man in black presses him. The man in white gives a sigh to the man in black to loosen his legs and expose legs' movements. They restore the original action, the man in white pulls down the man in black,and puts his leg across the man in black. man in white explains the action shortly, turns over and presses the man in black to the ground.
Human 5
a man in white lies on the ground, a man in black lies on him,the man in white points,and explains where to puts hands and feet.and then demonstrates how to turn over the man in black, and man in white continues to show how presses man in black under his body, and shows how to controls the hands of his opponent. The two separate.
Unified Consensus Groundtruth (UCG)
In a judo field, a man in black demonstrates various techniques on a man in white. The man in white lies on the ground as the man in black manipulates his limbs and demonstrates how to control the opponent. They go through the actions of turning over, pressing down, and locking arms before separating.
A conversation across alternating shots
Five independent human descriptions
Human 1
A white dress man holds a bell and looks at the camera. The man wearing a down jacket looks at the camera and speaks. The man shakes the bell. Screen switches back and forth. The man sits on the couch and speaks with a microphone.
Human 2
A man in the room holds a camera and talks.The man wears a gray coat. Another man sits on the couch.The man shakes the bell in the hands.The man wears a white sweater. The man speaks to microphone.The man takes photographs of the part below his head with the phone.
Human 3
A white dress man looks at the camera. A gray dress man talks to the camera.The white dress man talks to the camera, and shakes the hands of the toys.The gray dress man talks.The white dress man talks and shakes the toy in hands .The gray dress man talks and the white dress man talks.The gray dress man talks and the white dress man holds the microphone to speak and shake hands. The gray dress man talks and the white dress man talks. The gray dress man nods and speaks.
Human 4
In a room filled with lanterns, a man's left hand holds a rattling in the face of the lens to say something. In the next picture, the man holds the self-timer opposite to himself.The name of the festival appears continuously above the screen.In the next picture the man holds the walkie -talkie in the right hand and still faces the lens and talks.
Human 5
A white dress man holds a bell. Indoors, a man wearing a gray coat talks.The white dress man talks and rattles bells. A man wearing gray clothes speaks. The man in white talks and rattles bells. The man in gray speaks.The white dress man talks and rattles bells. The gray dress man speaks. The white dress man puts a black object in front of his mouth, shakes his hand and smiles.The man in gray speaks and the white dress man talks. The gray dress man nods and smiles.
Unified Consensus Groundtruth (UCG)
A man in a white dress holds a bell and talks to the camera, while another man in a gray coat also speaks. They take turns speaking and shaking the bell. The man in white also holds a microphone and shakes a toy. In a room filled with lanterns, the man takes selfies and holds a walkie-talkie while continuing to talk to the camera.
September 2026: page content aligned with the current manuscript, including twelve-model coverage, revised evaluation results, and event-level examples.
7 November 2025: project content and experimental analyses updated.